A practitioner’s guide to AI-assisted coding — what actually works, what the research shows, and where to be careful. No hype, just signal.
- AI coding tools genuinely help — the controlled study evidence is solid. The 2022 Peng et al. experiment (GitHub/MIT/Penn) found developers using Copilot completed tasks ~55% faster. More recent work from GitHub’s own research shows readability improving ~3.6% and maintainability ~2.5%.
- The dark side is real too. GitClear’s 2025 analysis of 211 million lines of code found refactoring activity dropped from 25% to under 10% since 2021, while copy-paste code grew. “AI-induced tech debt” is not a marketing term — it’s measurable.
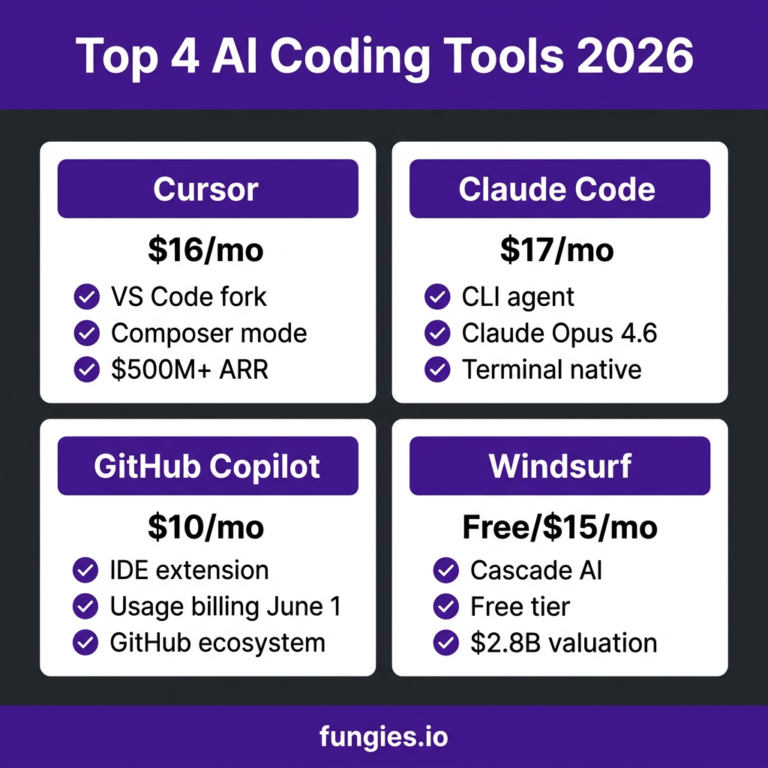
- The tools that matter most right now for clean code are: GitHub Copilot (enterprise standard), Cursor (developer favourite), Claude Code (strongest for complex reasoning), and SonarQube (static analysis layer). They serve different jobs — don’t treat them as interchangeable.
- Prompting quality is the bottleneck, not the AI model. A vague prompt returns vague code. Specific, context-rich prompts with constraints produce code you actually want to ship.
- Blindly trusting AI output is dangerous. Code review is not optional. The DORA 2025 report found ~30% of developers report little to no trust in AI-generated code — that instinct is reasonable and worth maintaining.
- The real productivity gain isn’t speed — it’s offloading the boring parts so you can think harder about the interesting ones.
- The reality check: what the data actually says
- The tool landscape in 2026
- The core workflow: how to actually use AI for clean code
- Prompting for cleaner code — the skill nobody talks about enough
- Using AI for refactoring and technical debt
- AI-assisted code review
- Testing and documentation
- The pitfalls most guides don’t mention
- Real-world cases and benchmarks
- FAQ
- Final thoughts
Before we get into how to use these tools, let’s be honest about what the research shows — including the parts that AI companies aren’t keen to highlight in their marketing copy.
The most-cited study in this space is the 2023 Peng et al. paper out of MIT, Penn, and GitHub itself. In a controlled experiment, developers using Copilot completed an HTTP server implementation in JavaScript 55.8% faster than the control group. That’s a striking number. It’s also a controlled, time-bounded task — which isn’t exactly representative of maintaining a 200,000-line production codebase over three years.
GitHub’s own 2024 research — which is worth reading even with the conflict-of-interest caveat — found code written with Copilot scored better in blind readability reviews. Developers wrote 13.6% more lines without hitting readability errors. Reliability improved by 2.94%, maintainability by 2.47%, and conciseness by 4.16%. Reviewers were 5% more likely to approve the code, meaning PRs merged faster.
On the other side, GitClear’s 2025 analysis is the most comprehensive independent look at code quality trends since AI adoption took off. Across 211 million changed lines of code between 2020 and 2024, they found a sharp and concerning pattern: the share of code categorised as refactoring dropped from 25% to under 10%, while copy-pasted code grew from 8.3% to 12.3% of all changed lines. Their interpretation is blunt — AI-generated code is “similar to a short-term developer that doesn’t thoughtfully integrate their work into the broader project.”
The DORA 2025 report adds a sobering macro note: while AI tool adoption has reached around 90% in some engineering organisations, roughly 30% of developers report little or no trust in the quality of AI-generated code. And Faros AI’s analysis found no significant correlation between AI tool adoption and company-level productivity gains. Individual developer velocity goes up. Business output — measured in shipped features, reduced bugs, faster delivery — hasn’t shown the same clear improvement at scale, at least not yet.
None of this means AI coding tools aren’t worth using. It means using them thoughtfully matters a great deal more than just using them at all.
There are more AI coding tools than anyone can realistically evaluate. Rather than listing fifty options, here’s an honest assessment of the ones that have proven durable and distinct.
Enterprise standard. Best legal cover (IP indemnity), deepest VS Code and JetBrains integration, custom model training on private repos.
Developer favourite for multi-file editing and agent-driven workflows. Supports Claude Opus 4, GPT-4. Best diff-review UX. Some billing friction emerged in mid-2025.
Terminal-based. Not an IDE plugin — a reasoning agent that reads files, writes files, runs commands. Strongest for complex multi-step tasks where understanding matters more than speed of autocomplete.
From Codeium (raised at $1.25B valuation, 2024). Best “agent-in-your-editor” feel. Lower friction migration from VS Code than Cursor. Strong enterprise case studies.
SonarQube / SonarLint
Not an AI code generator — an AI-enhanced static analysis tool. Essential for catching bugs, code smells, and security issues before they leave your machine. The IDE extension is free and underused.
CodeRabbit
AI-driven PR review. Analyses pull requests end-to-end, adapts to team coding patterns over time, reduces false positives. Good complement to any generation tool.
| Tool | Best For | Code Quality Features | Price (2026) | Code Review? |
|---|---|---|---|---|
| GitHub Copilot | Enterprise, IDE autocomplete | Inline suggestions, chat, PR review | Free / $10 / $39 per user | Yes |
| Cursor | Multi-file agent editing | Composer, multi-model support | Free / ~$20/mo | Partial |
| Claude Code | Complex reasoning, terminal | Deep codebase understanding | Usage-based (API) | Yes |
| Windsurf | VS Code users, free trial | Cascade agent, in-editor | Free / $15/mo | Partial |
| SonarQube IDE | Static analysis, security | Rule engine, code smell detection | Free (IDE plugin) | Yes |
| CodeRabbit | PR review automation | Team-adaptive review | Free / $12/seat | Core feature |
One thing worth saying clearly: the independent comparisons (Built In, MindStudio, Dan Cumberland Labs) consistently find that on raw code generation, the four major tools — Copilot, Cursor, Claude Code, Codex — perform roughly the same. Where they diverge is in reasoning quality for complex tasks, multi-file understanding, and agentic autonomy. Don’t pick a tool based on a synthetic benchmark alone.
3. The core workflow: how to actually use AI for clean code
The biggest mistake I see developers make is treating AI as a text-completion button. You type something vague, hit Tab, get vague code, paste it in, move on. That produces exactly the kind of “short-term developer” code GitClear’s research describes.
The workflow that produces cleaner output looks more like this:
Define constraints before you generate
Tell the AI what not to do, not just what to do. Specify language version, framework constraints, error handling style, whether you want sync or async, whether performance or readability is the priority. The model will make assumptions otherwise — and those assumptions may not match your codebase.
Generate in small units, not big blobs
Ask for one function at a time. One class. One module. Large generations accumulate errors and make review impossible. Small generations are easier to understand, easier to test, and easier to reject if they’re wrong.
Review before you run
Read the code. Not skim — read. If you can’t explain what every line does, you shouldn’t ship it. This sounds obvious; almost nobody does it consistently once they get comfortable with AI tools. This is exactly where dependency and tech debt begin.
Ask the AI to critique its own output
Before you accept code, paste it back and ask: “What are the weaknesses in this implementation? What edge cases could break it? How would you refactor this for better maintainability?” This prompt pattern consistently surfaces issues the initial generation missed.
Run static analysis as a gate
SonarLint in the IDE, plus a linter appropriate to your stack (ESLint, Ruff, Clippy, etc.) should flag issues before code review. Don’t ask a human reviewer to catch what automated tools should catch first. This is especially important with AI-generated code, which may pass visual inspection but fail on edge cases or security checks.
4. Prompting for cleaner code — the skill nobody talks about enough
Prompting is now a core engineering capability. It sits alongside git, debugging, and algorithmic thinking. The people getting the most out of AI coding tools aren’t the ones with the most expensive subscriptions — they’re the ones who’ve spent time learning to write good prompts.
Here’s the structure that consistently produces better code output:
The anatomy of an effective code prompt
That’s a lot more text than “write a function to parse this CSV.” But it takes 45 seconds to write and saves you 20 minutes of debugging mismatches between what you got and what you needed.
Prompts for specific clean-code tasks
Different tasks need different prompt shapes. Here are the ones that work reliably:
5. Using AI for refactoring and technical debt
This is one of the most genuinely high-value uses of AI in development — and it’s where most guides underinvest. Refactoring is tedious. It requires holding context about the full codebase, understanding intent not just syntax, and making conservative changes that don’t break existing behaviour. AI handles the mechanical parts of this well, once you know how to direct it.
What AI handles well in refactoring
- Renaming variables and functions for clarity across a file or module
- Extracting repeated logic into reusable functions
- Converting imperative code to more functional patterns (or vice versa)
- Adding type hints to untyped Python/JavaScript code
- Breaking large functions into smaller, single-purpose ones
- Applying consistent error handling patterns throughout a file
What AI does not handle well in refactoring
- Cross-file refactoring where intent is ambiguous (it will guess, often wrongly)
- Removing code that looks unused but is called dynamically
- Performance refactoring without profiling data
- Any refactoring that requires understanding business logic
Claude Code and Cursor Composer handle multi-file refactoring better than the others — both can read a broader slice of the codebase and maintain context across files. But even then, always run your test suite immediately after an AI-assisted refactor. Never assume it’s clean.
The refactoring workflow that works
# Step 1: Inventory
"Analyse this module and list: all functions, their purpose,
 any obvious code smells, and which functions are doing too much."

# Step 2: Plan
"Based on your analysis, propose a refactoring plan.
 List the changes in priority order, with rationale for each."

# Step 3: Implement one change at a time
"Implement change #1 from your plan.
 Show me the before and after, and explain what you changed and why."

# Step 4: Verify
"What tests should I run to verify this refactoring didn't break anything?
 What edge cases should I check manually?"
This sequence takes longer than asking for “a refactored version of this file.” It produces dramatically better results, and you actually understand what changed.
6. AI-assisted code review
Code reviews are one of the highest-leverage activities in software development. They catch bugs, spread knowledge, maintain architectural consistency, and prevent tech debt from accumulating invisibly. They’re also slow, mentally taxing, and easy to do poorly when a reviewer is tired or overloaded.
AI doesn’t replace human code review. It does make it faster and more consistent if you use it right.
The layered review approach
The most effective teams I’ve seen use a three-layer approach:
- Automated gates: linters, formatters, type checkers, security scanners. These run on every commit. They catch the obvious stuff so humans don’t have to.
- AI review: Tools like CodeRabbit or Copilot’s PR review feature analyse the diff for bugs, anti-patterns, and architectural concerns. This surfaces a second category of issues.
- Human review: Focused on architecture, business logic correctness, and things that require actual domain knowledge. This is where experienced engineers add the most value — and where they should spend their limited time.
Effective prompts for AI code review
If you’re using a chat-based AI rather than a dedicated review tool, these prompts produce the most useful output:
7. Testing and documentation
Two areas where AI is demonstrably useful and underutilised: writing tests and generating documentation. Neither is glamorous. Both are consistently neglected when teams are under time pressure. AI can shoulder a surprising amount of this load.
Test generation
AI tools are reasonably good at generating unit tests once you give them the function signature, purpose, and the edge cases you care about. What they’re not good at is identifying which edge cases matter — that still requires domain knowledge.
# Prompt: "Generate pytest tests for this function.
# Include: happy path, edge cases for empty input,
# None values, boundary conditions, and expected exceptions."

import pytest
from mymodule import parse_user_age

class TestParseUserAge:
    def test_valid_age(self):
        assert parse_user_age("25") == 25

    def test_boundary_min(self):
        assert parse_user_age("0") == 0

    def test_boundary_max(self):
        assert parse_user_age("150") == 150

    def test_empty_string_raises(self):
        with pytest.raises(ValueError):
            parse_user_age("")

    def test_none_raises(self):
        with pytest.raises(TypeError):
            parse_user_age(None)

    def test_negative_raises(self):
        with pytest.raises(ValueError):
            parse_user_age("-1")
That’s useful output. Notice what the prompt did: it specified the testing framework, the types of cases to cover, and the expected exception behaviour. Without that context, AI test generation produces generic, shallow tests that inflate coverage without improving confidence.
Documentation generation
AI is very good at writing docstrings, README sections, and inline comments. It’s less good at writing architectural decision records (ADRs) or any documentation that requires knowing why a decision was made, not just what the code does.
A simple pattern that works: run your AI tool over a module with the prompt “generate a docstring for each function that explains: what it does, what each parameter is, what it returns, and what exceptions it can raise.” Then read every docstring before committing. The AI sometimes misunderstands intent — but it’s faster than writing from scratch and easier than a blank page.
8. The pitfalls most guides don’t mention
This is the section that will save you the most headaches if you read it carefully.
Skill atrophy is a documented risk
This is perhaps the most uncomfortable finding in the research. When developers stop solving certain classes of problems manually, their ability to solve those problems degrades. Junior developers who use AI from the start of their careers may never build certain debugging muscles at all. The 2025 research from ICEIS includes a direct warning about “excessive dependency.” This isn’t a theoretical concern — it’s a pattern researchers are actively documenting now.
The practical implication: deliberately solve some problems without AI assistance. Keep the skills sharp. This matters less for senior engineers who already have strong mental models, and more for developers early in their careers.
Context window limitations cause subtle bugs
AI coding tools understand what you show them. When you’re working in a large codebase and you share one file at a time, the AI has no way of knowing that a variable name you’re using also appears in a different module with a completely different type. It will write code that looks correct in isolation and breaks in integration. The tools with larger context windows (Claude Code, Cursor with large-context models) handle this better, but “better” is not “perfectly.”
The copy-paste trap
GitClear’s data is clear: copy-paste code is growing, and it’s growing faster in codebases that use AI tools heavily. The temptation is to take AI-generated code, adjust it slightly, and paste a second version nearby rather than extracting a shared function. This is how codebases silently degrade. Every time you paste AI code, ask: “Should this be a function instead?”
Security blind spots
AI models are not security-first tools. They’re trained to produce code that works, not necessarily code that’s secure. Common issues that AI-generated code misses: SQL injection via string concatenation rather than parameterisation, missing auth checks on endpoints, sensitive data in log statements, and race conditions in concurrent code. Static analysis tools (SonarQube, Snyk, Semgrep) catch many of these. Running them is not optional if you’re shipping AI-generated code.
9. Real-world cases and benchmarks
Case: Accenture internal developer productivity study (~450 developers)
Accenture ran an internal evaluation of Copilot across approximately 450 developers. The study found both higher throughput and higher quality from developer teams. Critically, productivity gains were not uniform — they varied significantly by developer experience level and by task type. Senior developers captured larger gains on boilerplate and documentation tasks; junior developers captured smaller gains but showed risks around over-reliance.
Source: Referenced in Smit et al., AMCIS 2024 Proceedings
Case: Real-world comparison — refactoring a React component
A published hands-on comparison (ToolBit.ai, 2025) tested Copilot, Cursor, and Claude Code against a 200-line React component with mixed concerns. The task: refactor it into clean, separated components.
Before
- 200-line component, mixed UI and business logic
- No tests
- Three concerns in one file
- Unclear props interface
After (Claude Code)
- Three focused components, auto-generated
- All imports and dependencies updated
- Unit tests written for each
- Full autonomy — no hand-holding required
Copilot and Cursor both refactored competently; Cursor’s diff UX was cleanest. Claude Code’s output was most complete but required the most context setup upfront. For ease of use on smaller tasks, Cursor won. For complete autonomy on complex tasks, Claude Code was ahead.
Source: ToolBit.ai, published August 2025 (real test, named authors)
The honest benchmark picture
The Built In comparison (published May 2026) makes a point worth quoting in spirit: on raw code generation, the four main tools are “about the same.” Where differentiation shows up is autonomy length, reasoning depth, and multi-file coherence. Cursor beats Claude Code on IDE ergonomics. Claude Code beats Cursor on planning and reasoning for complex problems. Copilot beats both on enterprise compliance and legal risk management. Windsurf beats all on free-tier generosity.
The other benchmark worth knowing: DORA 2025 puts AI coding tool adoption around 90% in engineering organisations — but a 2025 Jellyfish review found 42% of companies abandoned most of their AI initiatives, and only 1% of US firms achieved measurable payback from AI investments. That number will improve as teams mature their workflows. But the early pattern is clear: adoption without deliberate workflow design doesn’t produce results.
FAQ
Does AI actually improve code quality, or just speed up writing bad code faster?
Both can happen, and which one you get depends almost entirely on how you use the tool. GitHub’s 2024 research showed statistically significant improvements in readability (3.6%), reliability (2.94%), and maintainability (2.47%) for code written with Copilot. But GitClear’s 2025 analysis of 211M lines of code found refactoring activity dropping sharply and copy-paste code growing. The honest answer: AI can improve quality if you use it thoughtfully and pair it with static analysis and real code review. Used carelessly, it accelerates technical debt.
Which AI coding tool is best for clean code specifically?
There’s no single winner. For refactoring complex, multi-file logic, Claude Code’s reasoning depth is the strongest. For inline autocomplete that respects your existing style, Copilot’s training on large codebases makes it the most context-aware. For a combined agent-plus-editor experience, Cursor’s Composer handles multi-file edits with the best diff UX. Pair any of these with SonarQube or SonarLint for static analysis — that combination catches what AI generators miss.
How long does it take to see productivity gains from AI coding tools?
One Medium analysis of 2024–2025 studies puts the honest answer at around 11 weeks before developers notice real productivity gains — and most people give up before then. The initial learning curve is real: you need time to develop good prompting instincts and learn when not to trust the output. Don’t evaluate AI coding tools after two weeks and conclude they don’t work.
Is AI-generated code secure enough to ship to production?
For most functionality — yes, with standard review. For security-sensitive code (authentication, payments, personal data handling, cryptography) — not without a dedicated security review by a human. AI models are not trained to be security-first; they’re trained to produce functional output. Common missed issues include missing input validation, SQL injection via string formatting, and missing auth checks on endpoints. Run SonarQube, Semgrep, or Snyk on any AI-generated code before it ships.
Will AI coding tools hurt my ability to code over time?
This is a real concern backed by emerging research, not just developer intuition. The ICEIS 2025 paper specifically flags “excessive dependency” as a risk. Skill atrophy is more of a concern for junior developers who never build certain problem-solving muscles in the first place. Deliberate practice — solving problems without AI assistance on a regular basis — is the practical mitigation. Don’t let AI become the only way you can write code.
How do I write better prompts to get cleaner AI-generated code?
The biggest lever is specificity. Specify language version, framework, error handling style, what to include and what to exclude, and what trade-off to prioritise (readability vs performance). Ask for type hints, docstrings, and test stubs explicitly — models won’t add them unless you ask. After generation, use a critique-then-improve prompt: ask the model what’s wrong with its own output before you accept it. This two-step approach consistently surfaces issues the initial generation missed.
Can AI do code review, or does it still require humans?
AI code review (via tools like CodeRabbit or Copilot’s PR review) is genuinely useful for catching common bugs, anti-patterns, and style issues. It’s not a replacement for human review. AI reviewers miss issues that require domain knowledge, business logic understanding, or knowledge of how the code integrates with external systems. The right model: AI handles the automated-checklist layer so humans can focus on architectural and business-logic review.
What’s the real ROI of AI coding tools for a team?
The honest answer is murkier than vendor marketing suggests. Individual developers write more code faster — that’s well-documented. Company-level productivity gains are harder to prove. Faros AI’s analysis found no significant correlation between AI tool adoption and company-level output. Jellyfish’s 2025 report found that for a 50-developer team, the true first-year cost (subscriptions plus training plus productivity dip during adoption) runs $150K–$180K, with most organisations achieving ROI within 2–4 years — not 2–4 months.
Should junior developers use AI coding tools?
Yes, but carefully. The productivity benefit is smaller for junior developers than for senior ones — junior devs lack the pattern recognition to evaluate AI output critically. The risk of dependency is higher. If you’re early in your career, use AI tools for boilerplate and documentation, but make yourself solve algorithmic and debugging problems manually before reaching for AI help. You need to build the mental models first, or you’ll have nothing to fall back on when the AI is wrong — which it regularly is.
What’s the best way to use AI for refactoring legacy code?
Break it into steps: first, have the AI inventory the code (list all functions, identify code smells, note what does too much). Second, ask it to propose a refactoring plan in priority order. Third, implement one change at a time and verify with tests before moving on. Never ask for “a refactored version of this entire file” in one shot — the result will be harder to review and easier to get wrong in ways that are hard to spot.
How do I prevent AI tools from increasing technical debt?
Four concrete habits: always review AI-generated code before accepting it; run static analysis on every AI-generated file; when AI suggests copy-pasting logic, extract a shared function instead; and periodically audit your codebase for “AI fingerprints” — excessive duplication, shallow refactoring, or copy-paste patterns. GitClear offers tooling for this. The discipline of refactoring has to be actively maintained when using AI, because the tools don’t do it naturally.
Is there a free setup that’s good enough for serious use?
Yes. Copilot’s free tier (2,000 completions/month) plus SonarLint (free IDE plugin) plus your existing linters gets you a solid foundation at zero cost. For larger projects, Windsurf’s free trial is the most generous in the market as of mid-2026. Claude’s free tier via claude.ai can handle one-off refactoring and review prompts. This stack covers most of what a solo developer or small team needs to use AI for cleaner code without a budget.
Final thoughts
AI coding tools have moved firmly past the “interesting experiment” stage. The productivity gains in controlled studies are real. The risks — skill atrophy, growing technical debt, security blind spots — are also real and well-documented. The deciding variable isn’t which tool you use. It’s how disciplined your workflow is.
The developers and teams that get the most out of these tools share a few characteristics: they review AI output carefully before accepting it, they invest in prompt quality, they keep static analysis as a non-negotiable gate, and they maintain human code review rather than replacing it. They also occasionally solve problems without AI, deliberately, to keep their own skills sharp.
The technology will keep improving. The judgment required to use it well won’t be automated away — not for a while. That judgment is what makes the difference between AI helping you write cleaner code and AI quietly accumulating tech debt on your behalf.
More from BestPrompt.Art
How to Generate Code With AI Prompts — Beginner to Pro
The AI Prompts Top Developers Use Every Day – Best Guide
AI Prompt Tricks to Instantly Improve Your Code
Prompt Engineering Guide for Developers | Master AI Prompts 2025 Meta
How to Write AI Prompts for Beginners in 2025
How Developers Use AI Prompts to Write Code Faster: BestGuide
How to Create Effective AI Prompts: Your Secret Sauce for Killer Content (With Real-Life Examples) 🔥
How to Create an Epic Contribution Guide: A Step-by-Step Journey
How AI Is Changing the Way Developers Write Code
What is an AI prompt? A Fun Dive into the World of AI Assistants
How to Create the Perfect Prompt: Best Guide for Beginners
The AI Prompts That Actually Work for Readers
Detailed Prompts in 2025: 10 Secrets for Better AI Results
The Guide to Writing Clear and Concise Prompts: Unlock the Power of Simplicity
AI Coding Assistants vs Human Programmers —Who Actually Wins?
How Beginners Can Build Apps With AI Prompts — Step by Step
Unleashing the Power of AI in Research Writing, Reading & Analysis: Your Ultimate Guide
25 AI Coding Prompts Programmers Use to Save Hours Every Week
How to Build Websites Faster With AI (Step-by-Step Guide)
AI Coding Prompts Developers Use to Save Hours: Best Guide
ChatGPT Prompts for Frontend Developers to Build Faster