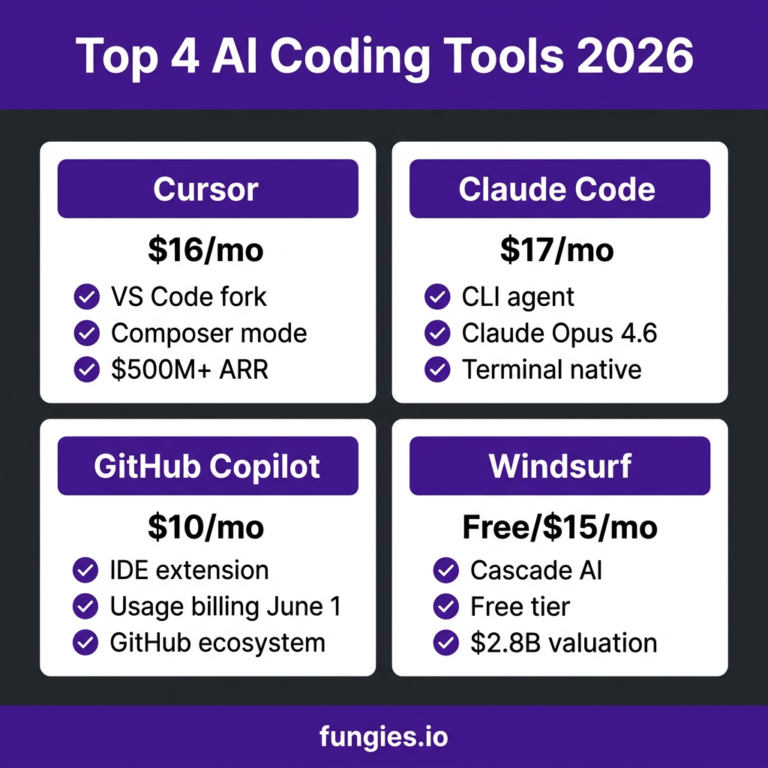
The gap between developers who get great results from AI and those who don’t isn’t the model — it’s the prompt. Here’s what actually works, backed by research and honest testing.
- The core problem: 84% of developers now use AI tools, but fewer than 30% report consistently useful output for production code — not because the models are bad, but because vague prompts produce generic code.
- The fix is structure, not cleverness. Every high-performing prompt contains: context about your codebase, a specific role or persona, the actual task, constraints, and (crucially) what you don’t want.
- Chain-of-thought has nuance. A June 2025 Wharton study found CoT helps non-reasoning models but adds overhead for models like o3 or Claude Sonnet 4.5 that already reason internally — match the technique to the model.
- Few-shot examples are the highest-leverage trick. Showing the AI two or three examples of your desired output style consistently outperforms long instructions about style.
- Negative constraints matter as much as positive ones. Telling the model what NOT to do (no global variables, no comments explaining obvious things, no changing the function signature) eliminates 80% of the frustrating rewrites.
- Realistic expectation: Good prompting won’t replace code review. GitHub Copilot users still see ~46% of code needing human review before merging — AI raises your ceiling, it doesn’t remove your judgment.
- Next step: Pick one technique from this guide today. The CRAFT framework in Section 2 is the highest ROI starting point for most developers.
Let me start with something uncomfortable. I spent the better part of six months frustrated at AI coding assistants. The output was mediocre — tutorial-level code that missed my architecture, ignored my conventions, and required more cleanup than if I’d just written it myself. I assumed the tools weren’t good enough.
Turns out, I was prompting badly. Once I understood how to actually communicate with these models — treating them less like search engines and more like very capable but context-blind junior developers — everything changed.
This guide is what I wish I’d had. It’s not about clever tricks or hacks. It’s about understanding what these models actually need to produce good output, backed by what the research says and what I’ve tested myself across real projects.
The numbers here are striking. Stack Overflow’s 2025 Developer Survey found that over 70% of developers use AI tools, but fewer than 30% report consistently useful output for production code. That’s a massive gap — and it’s not getting filled by model upgrades alone.
That last stat is worth sitting with. Most developers give up before the productivity gains materialize. Part of that is tool familiarity — but a bigger part is that without good prompting habits, the early results genuinely aren’t great, and it’s easy to conclude the tool isn’t worth it.
What the AI models lack isn’t intelligence — modern LLMs can reason through surprisingly complex problems. What they lack is your context. They don’t know your codebase, your team’s conventions, your deployment constraints, or what “clean” means to you. Every vague prompt forces the model to guess on all of those dimensions simultaneously. And when it guesses wrong on three out of five, the output lands in the bin.
“The developers getting the most value from AI in 2026 aren’t the ones typing ‘write code for X.’ They’re the ones who’ve learned to communicate with AI effectively.”
— aiagentskit.com, Essential Code Prompts Guide, 2026Several frameworks have floated around — CRTSE, RCCF, and others. After testing them across different models and task types, I’ve converged on something I call CRAFT, which I find easier to remember and apply consistently:
- C — Context: What codebase, language, stack, and constraints are you working in?
- R — Role: What kind of expert should the model act as?
- A — Action: The specific task, as concrete as possible.
- F — Format: How should the output be structured?
- T — Taboo: What should it explicitly NOT do?
The “Taboo” element is the one most developers skip, and it’s often the most valuable. More on that in the next section. First, here’s what the difference looks like in practice:
Write me a function that processes user orders.
Context: Python 3.12 FastAPI service, PostgreSQL via SQLAlchemy 2.0, async/await throughout. We follow PEP 8 strictly, type hints on everything, no bare except clauses.

Role: You're a senior backend engineer who cares about error handling and testability.

Action: Write an async function process_order(order_id: UUID, db: AsyncSession) that fetches the order, validates its status is "pending", deducts inventory atomically, and transitions the order to "confirmed". Handle the case where inventory is insufficient.

Format: Function with full type annotations, docstring, inline comments only where non-obvious. Raise custom exceptions defined in exceptions.py.

Don't: Add logging (we handle that via middleware), don't use global state, don't write tests (separate request).
The second prompt takes maybe 90 seconds to write. The output from the second prompt is usually mergeable. The output from the first needs a complete rewrite. That time math favors the longer prompt every single time.
Save a CRAFT template as a snippet in your editor. Fill in the blanks for each request rather than starting from zero. Over time you’ll have project-specific templates that take 20 seconds to complete.
This is genuinely the most underused technique I know. The “T” (Taboo) in CRAFT — explicitly telling the model what NOT to do — eliminates a whole category of frustrating outputs.
When you don’t constrain the output, the model defaults to patterns that are common in its training data: over-commented code, global variables for convenience, inconsistent error handling, adding print statements for debugging, changing function signatures without asking. These are all reasonable choices in isolation. They’re just not your choices.
# General negative constraints worth keeping in your template:

Don't:
- Change the existing function signatures or class interfaces
- Add comments that just restate what the code does ("# increment counter")
- Use global variables or module-level state
- Add print() or console.log() debugging
- Import libraries not already in the project (ask first)
- Change indentation style or quote style (we enforce via linter)
- Add try/except blocks around everything — only catch what you can handle
- Explain what you did after the code block, just provide the code

For refactoring specifically, also add:
- Don't change the external behavior of the function
- Don't rename public methods or properties
- Don't split into multiple files unless explicitly requested
There’s an important nuance here. You want constraints that are genuinely yours, not generic boilerplate. Take five minutes at the start of a project to think through what annoys you most about AI-generated code, and put those things in your Taboo list. The more specific it is to your actual preferences, the more useful it becomes.
If I had to pick one technique that consistently produces the biggest improvement in output quality, it’s few-shot prompting. The idea is simple: instead of describing the style you want, you show the model two or three examples of code you’ve already written that represent that style.
This works because style is genuinely hard to describe in words. “Clean, idiomatic Python” means something different to everyone. But if you paste two functions from your actual codebase as examples, the model picks up on your naming conventions, docstring format, error handling patterns, and level of abstraction immediately — things that would take paragraphs to specify in prose.
# Structure: explain task, then provide examples, then give new task

I need you to write a new data validation function.
Match the style of these two existing functions from our codebase exactly:

--- EXAMPLE 1 ---
async def validate_user_email(email: str) -> ValidationResult:
    """
    Validate email format and domain against allowlist.

    Args:
        email: Raw email string from request

    Returns:
        ValidationResult with .is_valid bool and .error Optional[str]

    Raises:
        ValueError: If email is None or empty string
    """
    if not email:
        raise ValueError("email cannot be empty")
    ...

--- EXAMPLE 2 ---
[paste second example]

--- NEW TASK ---
Now write validate_phone_number(phone: str) -> ValidationResult
following the exact same patterns. It should check E.164 format
and reject numbers from blocked country codes in settings.BLOCKED_COUNTRIES.
One practical limitation: few-shot prompting costs more tokens, and for very long examples, you may hit context limits. The solution is to trim your examples down to the essential patterns — you don’t need the full function body, just enough to establish the style.
A January 2026 study from arxiv (Guidelines to Prompt LLMs for Code Generation) confirmed that providing concrete examples consistently outperforms descriptive instructions for style transfer in code generation tasks — across languages and model sizes.
Chain-of-thought prompting — telling the model to “think step by step” before answering — has been popular since 2022. But the picture is more complicated than it looks, and blindly applying it to every coding prompt is a mistake.
A June 2025 Wharton study (Prompting Science Report 2, Meincke et al.) tested CoT across multiple models and found something interesting: for non-reasoning models, CoT generally improves average performance by a modest amount, but also increases variability — sometimes causing errors on questions the model would have gotten right without it. For reasoning models like o3 or Claude Sonnet 4.5 that already do internal reasoning before responding, the gains are marginal and the latency cost is real (20–80% more tokens).
| Scenario | Use CoT? | Why |
|---|---|---|
| Designing a complex algorithm from scratch | Yes | Multi-step reasoning benefits from explicit decomposition |
| Debugging a non-obvious bug | Yes | Ask it to list possible causes before proposing a fix |
| Simple boilerplate generation | No | Adds latency without meaningful quality improvement |
| Using o3 or Claude Sonnet 4.5 | Optional | Model already reasons internally; CoT adds mostly token cost |
| Security review of a codebase | Yes | “List potential vulnerabilities before suggesting fixes” works well |
| Generating unit tests for a clear function | No | Direct prompt with constraints works better here |
| Architecture decisions with trade-offs | Yes | “Walk through the trade-offs before recommending” surfaces useful analysis |
The practical version of CoT for coding isn’t just “think step by step.” It’s more targeted phrases like: “Before writing the code, list the edge cases you’ll handle” or “Describe your approach in two sentences before implementing it.” This gives you something to review before 50 lines of code appear, and it’s cheaper than a full reasoning chain.
Debugging is where most developers start using AI — and where frustrating results are most common. The problem is usually the same one: pasting an error message and hoping for magic. The model has no idea what the code around that error is doing, what you’ve already tried, or what “fixed” looks like.
A debugging prompt that actually works needs four things: the error (full stack trace, not just the message), the relevant code, your current hypothesis, and what you’ve already tried. That last two are the ones people skip. They force you to articulate your mental model, which often surfaces the bug before the AI even responds — and they help the model focus on hypotheses you haven’t tested.
## Debugging Request

**Error (full traceback):**
```
AttributeError: 'NoneType' object has no attribute 'user_id'
  File "api/orders.py", line 47, in create_order
    user = await get_user(order.user_id)
  File "api/users.py", line 23, in get_user
    return result.scalar_one_or_none()
```

**Relevant code:**
[paste the function and any directly called helpers]

**My current hypothesis:**
I think get_user is returning None when the user_id is valid but
the session is already closed — but I'm not certain.

**What I've already tried:**
- Added a null check before calling create_order (didn't fix it)
- Verified the user_id exists in the database (it does)
- Checked the SQLAlchemy session scope (looks correct to me)

**What I need:**
List the most likely root causes ranked by probability, then
suggest the fix for the most likely one. Don't rewrite the
whole function unless the bug requires it.Writing out “what I’ve already tried” is essentially rubber duck debugging on steroids. I’ve had the experience of typing out my attempted solutions and realizing mid-sentence that I’d missed something obvious. The AI doesn’t even get a chance to answer — which is, in a weird way, the best outcome.
Refactoring is one of the highest-value use cases for AI coding assistance, and also one of the most dangerous. The risk: the model changes external behavior while refactoring internal structure, or introduces subtle bugs in the process of improving readability. Constraints are critical here.
Refactor this function for readability and maintainability.

Constraints (these are hard requirements):
- Do NOT change the function signature or return type
- Do NOT alter the external behavior — all existing tests must still pass
- Do NOT rename public methods or the function itself
- Do NOT split into multiple files
- Do NOT add new dependencies

Goals (in priority order):
1. Reduce nesting depth (currently 4 levels in some paths)
2. Extract the validation logic into helper functions
3. Improve variable names — most are single letters

Language/Style:
Python 3.12, PEP 8, type hints required on all helpers

[paste the function here]

After refactoring, briefly list what you changed and why.
Then provide a diff-style view of the key changes.
For code review, the trap is asking for generic feedback and getting a wall of minor nitpicks. A better approach is to specify what kind of review you want, because a security review, a performance review, and a readability review are completely different tasks:
# Security-focused review:
Review this code for security vulnerabilities only.
Focus on: SQL injection, authentication bypass, insecure deserialization,
secrets in code, and improper input validation.
For each issue: severity (Critical/High/Medium/Low), location,
explanation, and a concrete fix. Skip style issues entirely.

# Performance review:
Review this code for performance issues in a production context
serving ~50k requests/day. Flag: N+1 queries, missing indexes
(describe what to add), unnecessary blocking calls, and memory
inefficiencies. Ignore anything that won't matter at this scale.

# Readability review:
Review this code as if you're a new team member encountering it
for the first time. Identify: unclear variable names, missing
docstrings for non-obvious functions, logic that would confuse
a competent Python developer, and any "clever" code that should
be made more explicit. Prioritize by how confusing each issue is.
8. Generating Tests You’ll Actually Trust
AI-generated tests have a reputation for being useless — passing tests that don’t actually test anything meaningful, or tests so tightly coupled to implementation that they break every refactor. The problem is almost always prompt-level: asking for “unit tests” without specifying what makes a good test for this function.
The key is to be explicit about your testing philosophy and what you want the test suite to prove:
Generate pytest tests for this function.

Testing philosophy:
- Test behavior, not implementation. Don't assert that specific
  private methods were called unless the side effect matters.
- Each test should have one clear assertion about one behavior.
- Tests should be readable as documentation.

Required coverage:
1. Happy path (typical valid input, verify correct output)
2. Boundary conditions (empty string, zero, None, max value)
3. Invalid input types (what should raise ValueError vs TypeError)
4. The specific edge case where [describe your known edge case]
5. Error conditions (what happens when the dependency fails)

Don't:
- Mock anything unless it makes an external network/DB call
- Add assertions about log output
- Generate tests longer than 10 lines each
- Use random or time-dependent values

[paste the function here]

Use pytest-style with descriptive test function names that read
like sentences: test_returns_empty_list_when_no_matches_found()| Test Type | Prompt Strategy | Common AI Mistake to Prevent |
|---|---|---|
| Unit tests | Specify behavior vs implementation, list edge cases explicitly | Testing internal implementation details that change on refactor |
| Integration tests | Describe the full user flow, specify what data to seed | Over-mocking, making tests useless for integration purposes |
| Security tests | Reference OWASP Top 10, specify the threat model | Happy-path security tests that don’t actually probe for vulnerabilities |
| Property-based tests | Specify the invariants that must always hold, not specific inputs | Generating fixed examples when the point is generative testing |
9. Context Management for Long Sessions
One of the most common complaints about AI-assisted coding: it “forgets” the context established earlier in the conversation and starts producing inconsistent code. This isn’t a mystery — models have finite context windows, and as a conversation grows, older information gets pushed out or weighted less heavily.
A few techniques that genuinely help:
The “Compact Project Brief”
At the start of any significant coding session, paste a brief technical summary of your project. Keep it under 300 words. Include: language and version, framework, architectural patterns you follow, key conventions, and what problem you’re solving. Reference it when you start new requests within the same session.
## Project Context (paste this at session start)

Stack: Python 3.12, FastAPI 0.115, SQLAlchemy 2.0 (async),
PostgreSQL 16, Redis for caching, pytest for tests

Architecture: Service layer pattern. Routes call services,
services call repositories, repositories call the DB.
No business logic in routes. No direct DB calls in services.

Conventions:
- All endpoints are async
- Type hints everywhere, no untyped parameters
- Pydantic v2 for request/response schemas
- Custom exceptions in exceptions.py, never raise generic Exception
- Logging via structlog, not the standard library
- 100% test coverage required for service layer

Current task: [describe what you're building today]
Reset Rather Than Persist
When a session has gone on for 10–15 exchanges and the model starts producing code that contradicts earlier decisions, don’t try to correct it inline. Reset. Start a new chat with your project brief plus a summary of decisions made so far. This is faster than trying to unfork a confused conversation.
Treating AI like it has persistent memory across sessions. It doesn’t. Every new conversation starts blank. Developers who build the habit of starting each session with a project brief get dramatically more consistent output than those who assume the AI “knows” the project from yesterday.
10. Model-Specific Differences Worth Knowing
Not all models respond identically to the same prompt. These differences are real and affect which techniques to lean on:
| Model | Strengths for Code | Weaknesses | Prompt Tip |
|---|---|---|---|
| Claude Sonnet 4.5 / Opus | Complex reasoning, long context, architecture discussions, nuanced refactoring | Can over-engineer simple tasks | Specify “keep it simple” explicitly; it respects constraints well |
| GPT-5 / o3 | Versatile, strong at multi-file work, good at following structured formats | Can be verbose in explanations | Add “code only, no explanation” when you want clean output |
| Gemini 2.5 Pro | Very large context window, good for whole-codebase analysis | Can be less opinionated about style | Be explicit about style — it benefits most from detailed examples |
| GitHub Copilot | Inline completions, context from open files, fast | Limited to what it sees in open editors | Open relevant files before requesting completions; it uses them as context |
The meta-lesson: don’t pick one model and assume it’s universally best. Use Copilot inline while you type, use Claude or GPT for architecture discussions and complex refactoring, and use Gemini when you want to analyze a large chunk of code at once. They’re genuinely complementary.
11. Real Results: What Actually Changed in My Workflow
I want to be honest about what these techniques do and don’t change, because I’ve seen too many guides make this sound like it eliminates all the friction of working with AI tools.
Before implementing structured prompting (roughly 18 months ago), my experience with AI coding assistance was: useful for boilerplate, frustrating for anything requiring judgment or context. I’d estimate about 30% of AI-generated code was usable with minor edits. The rest required either significant rework or was faster to write from scratch.
After building consistent prompting habits — specifically the CRAFT structure, negative constraints, few-shot examples for style-sensitive tasks, and project briefs at session start — that number is closer to 70% usable with minor edits. And the tasks where AI is most useful have expanded significantly: I now use it for refactoring, security review, test generation, and architectural brainstorming, not just boilerplate.
What didn’t change: I still review every line of AI-generated code before merging. I still catch bugs the AI introduced. I still have sessions where the context gets confused and I have to reset. The productivity gain is real — GitHub’s research showed 55% faster task completion in controlled studies, and that feels roughly right for my experience — but it’s not magic, and it requires active management.
“AI raises your ceiling, it doesn’t remove your judgment. The developers who get burned are the ones who mistake speed for correctness.”
— From my experience across ~40 production features using AI assistanceThese techniques won’t fully compensate for a genuinely under-specified task. If you don’t know what you want to build, AI will confidently build the wrong thing. Prompting skill amplifies your clarity — it doesn’t replace it.
Frequently Asked Questions
Does prompt engineering still matter now that models are so capable?
More than ever, actually — but for different reasons. Better models don’t reduce the value of good prompts; they amplify it. A well-structured prompt to GPT-5 or Claude Sonnet 4.5 gets dramatically better output than a vague one, because the model has more capability to actually fulfill detailed specifications. The gap between good and bad prompts grows as models improve.
Which AI model is best for coding in 2026?
Genuinely depends on the task. Claude Sonnet 4.5 and Opus are strong for complex reasoning and long context. GPT-5 handles multi-file tasks well. Gemini 2.5 Pro has the largest context window for whole-codebase analysis. GitHub Copilot wins for inline completions while typing. Most experienced developers use 2–3 tools depending on the task rather than committing to one.
How long should a prompt be?
As long as it needs to be to specify the task unambiguously — and not a word longer. For simple boilerplate, 2–3 sentences is fine. For complex refactoring or new feature development, a few paragraphs is appropriate. The mistake isn’t writing long prompts; it’s writing long prompts that don’t add useful information (padding, repetition, unnecessary explanation).
Should I trust AI-generated code in production?
With review, yes. Without review, no. AI-generated code contains bugs at a lower rate than junior developer code in most benchmarks, but it contains different kinds of bugs — often subtle logic errors that pass basic tests. Treat AI output as a capable draft that still requires engineer review, not as a finished product.
What’s the biggest mistake developers make when prompting for code?
Providing context about the output they want but not the context about their environment. “Write me a function that does X” is under-specified because the model doesn’t know your language version, your architecture patterns, your error handling conventions, or what style you consider clean. The model guesses — and guessing on five dimensions simultaneously produces generic output.
Is chain-of-thought prompting worth it for coding tasks?
It depends on the model and the task. For complex algorithmic design or debugging non-obvious bugs, yes — asking the model to reason through the problem before coding it genuinely improves output quality. For simple boilerplate or when using reasoning models like o3 that already think internally, the overhead usually isn’t worth it. A June 2025 Wharton study confirmed this nuance (see Section 5).
How do I stop AI from changing things I didn’t ask it to change?
Negative constraints. Explicitly list what must not change: function signatures, file structure, naming conventions, external behavior. Models respect “do not” instructions well when they’re specific. Vague instructions like “keep it similar” are interpreted loosely; “do not rename any public methods or change any function signatures” is much harder to violate accidentally.
Can AI prompting help with legacy code?
Yes, and it’s one of the better use cases. Give it the legacy function with full context about what it’s supposed to do, and ask for a refactored version with the same external behavior. The key is being explicit that it cannot change signatures or behavior — and generating comprehensive tests before refactoring so you can verify the behavior is preserved.
How do I handle AI “hallucinating” libraries or APIs that don’t exist?
Constrain to your known dependencies. Include a “only use libraries already imported in this file” or “only use functions from [library name] version X.Y” constraint. When the model suggests something unfamiliar, always verify it against official documentation before using it — hallucinated method names are one of the most common errors in AI-generated code.
How much time does building good prompt habits actually save?
The time investment to write a structured prompt is usually 60–90 seconds versus 10 seconds for a vague one. The output from a structured prompt typically requires 5–10 minutes of review and minor edits; a vague prompt often requires 20–40 minutes of significant rework or complete rewriting. The math strongly favors the upfront investment. This aligns with GitHub’s research showing a 55% task completion speedup across a study of 4,800 developers.
Should I use AI for architecture decisions?
As a brainstorming partner and trade-off articulator, yes. As a decision-maker, no. AI is genuinely useful for exploring “what are the trade-offs between approach A and approach B” because it can synthesize considerations quickly. But architecture decisions carry context about your team’s skills, your org’s risk tolerance, and your operational constraints that the model doesn’t have — and those factors often outweigh technical considerations.
Is there a risk of becoming too dependent on AI for coding?
Yes, and it’s a documented concern. Analysis of GitHub Copilot usage patterns noted that junior developers in particular can become over-reliant on AI suggestions without fully understanding the code they’re merging — a dynamic that can slow long-term skill development. The healthy approach is using AI to accelerate tasks you understand, and deliberately working through unfamiliar problems manually to build foundational knowledge.
More from BestPrompt.art
- The Complete Prompt Engineering Guide (2026)
- Best Claude Prompts for Developers
- ChatGPT Coding Prompts That Actually Work
- How to Use AI for Code Review Without Getting Burned
- Few-Shot Prompting: The Complete Developer’s Guide
- Prompt Templates Library for Developers
- Debugging with AI: The Right Way
- Generating Tests with AI That You Can Actually Trust
- System Prompts: A Practical Guide for Developers
- Best Cursor IDE Prompts (Updated 2026)
Final Thoughts
None of this is magic. The CRAFT framework, negative constraints, few-shot examples, targeted chain-of-thought — these are just ways of giving the model the information it needs to do what you actually want. They work because they’re aligned with how these systems function, not because they trick the model into performing better.
The developers I know who get the most out of AI coding tools treat them like capable team members who are new to the codebase. You wouldn’t hand a talented new hire a ticket that says “fix the order processing thing” and expect great results. You’d give them context, explain the constraints, point them to examples, and tell them what not to do. Same principle applies here.
Start with one technique. The CRAFT structure is the highest-leverage starting point for most people — just adding the Context and Taboo elements to your existing prompts will visibly improve output quality. From there, few-shot examples for style-sensitive tasks, targeted CoT for complex reasoning, and structured debugging templates will compound the gains.
The gap between developers who prompt well and those who don’t will widen as models become more capable. The investment pays off now and keeps paying.
Password Reset