You Think You Understand AI Prompts for Business Growth. You Understand the Brochure.


AI Prompts for Business: What the Primary Research Actually Shows — and Six Prompts Built to the Same Standard
Updated September 2026. Every statistic below links to its primary source. Claims that can’t be verified against a source we don’t control are labeled by evidence tier or omitted.
The reversal, in numbers (Adobe Digital Insights, August 2026)
Twelve months ago, visitors arriving at U.S. retailers from AI assistants converted at roughly half the rate of other channels. As of July 2026, the gap has inverted:
| Metric (AI-referred vs. non-AI retail traffic, July 2026) | One year ago | Now |
|---|---|---|
| Conversion rate | ~50% of other channels | +60% higher |
| Revenue per visit | non-AI worth 128% more | AI worth +53% more |
| Traffic growth | — | +62% year over year |
Source: Adobe Digital Insights, AI Traffic Trends Report, August 2026, based on more than 1 trillion visits across 130+ leading U.S. retailers. AI-referred visitors also spent 59% more time on site, viewed 22% more pages, and were 34% less likely to bounce.
Two caveats before anything else: these are U.S. retail figures, not a cross-industry average; and “AI-referred” counts only visitors who clicked a link inside an AI answer. It misses buyers who got their answer and never clicked — which SparkToro’s zero-click research suggests is a large and growing share.
What the primary research says
The adoption/impact gap (McKinsey, 2025)
McKinsey’s 2025 global AI survey — nearly 2,000 respondents across 105 countries — remains the most recent large-scale primary data on enterprise AI adoption with a full methodological appendix.
| McKinsey, “The State of AI: Global Survey 2025” (n=1,993) | Share |
|---|---|
| Use AI regularly in at least one function | 88% (up from 78% prior year) |
| Report any enterprise-level EBIT impact | 39% |
| Qualify as “AI high performers” (5%+ EBIT impact) | ~6% |
Source: McKinsey, The State of AI.
One correction to a framing you’ll see elsewhere: subtracting 6% from 88% to claim an “82-point gap” is invalid — the numbers answer different questions on different populations. The legitimate contrast is 88% adoption versus 39% reporting any EBIT impact. That 49-point drop-off is the story, and it’s bad enough without embellishment.
What separates the high performers: not model choice or budget. McKinsey tested 25 organizational attributes and found that redesigning workflows around AI — rather than bolting AI onto an existing process — had the single biggest effect on whether EBIT impact appeared at all (McKinsey, “How Organizations Are Rewiring to Capture Value”). High performers are more than three times as likely to be pursuing transformational change, and roughly half are actively rebuilding the workflow itself.
Why pilots stall (MIT Project NANDA)
MIT’s 2025 GenAI Divide report found that 95% of generative AI pilots failed to deliver a measurable P&L impact, based on ~300 public deployments, executive interviews, and a leader survey (as reported by Forbes and Fortune).
Be precise about what that number measures: pilots producing no rapid P&L impact — a narrow bar, and researchers have pushed back on how widely the framing has been applied. Treat it as directionally right, not gospel. The mechanism the MIT team identified is a “learning gap”: generic tools are flexible enough to shine in demos but don’t adapt to a specific company’s workflow, so they stall in production.
The pattern that predicts success is narrowness. MIT researcher Aditya Challapally contrasted young-founder startups reaching eight-figure revenue within a year — not through superior technology, but by picking one specific, painful problem and executing on it well — with enterprise pilots trying to be broadly “AI-powered.” Pilots aimed at one narrow, well-defined workflow succeed far more often.
AI is now a discovery channel
The fastest shift is happening on the demand side: people increasingly ask AI assistants for recommendations instead of typing into a search box.
| Period | AI-referred retail traffic (YoY) | Conversion vs. non-AI |
|---|---|---|
| Nov–Dec 2025 holiday season | +693% average; peaked at +1,151% in December | Roughly half the rate of other channels |
| Q1 2026 | +393% | +42% better |
| May 2026 | +138% | +54% better |
| July 2026 | +62% | +60% better |
Growth rates compress as the base grows — that’s a channel normalizing, not slowing. Sources: Adobe Q1 2026 report, Digital Commerce 360, Adobe August 2026 report.
The mechanism: someone clicking through from an AI assistant has usually already compared options and asked follow-ups. The click is the last step of a decision, not the first. Adobe’s July 2026 consumer survey supports this: 42% of consumers have used AI assistants for online shopping, and 66% say they visit a brand’s website directly to verify an AI recommendation before buying. Marketers report the same — HubSpot’s 2026 State of Marketing found 58% say AI-referred visitors convert at higher rates than traditional organic traffic.
The Princeton finding that anchors all of this
In 2024, researchers from Princeton, Georgia Tech, IIT Delhi, and the Allen Institute for AI published the first large-scale controlled study of content modifications and AI-answer visibility (Aggarwal et al., “GEO: Generative Engine Optimization,” KDD 2024 — arXiv). Across nine tactics and ~10,000 queries:
- Statistics Addition (specific numbers with sources): up to +40% visibility
- Quotation Addition (direct, attributable quotes): up to +41% on the position-adjusted metric
- Cite Sources (references to credible third parties): up to +115% for pages ranked 5th in traditional search — GEO disproportionately helps smaller brands that SEO disadvantages
- Keyword stuffing performed worse than doing nothing
A scope note the rest of the internet ignores: the study measured visibility on benchmark queries. It did not establish word-count ratios, optimal fact density, or time-to-impact figures. Those numbers circulating in AEO content are heuristics or vendor claims. Where this article uses a heuristic, it says so.
Case studies — labeled honestly
From HubSpot’s published AEO case studies. Tier C evidence: numbers produced by the agencies that did the work. The tactical patterns match the Princeton findings, which is the main reason they’re worth attention; treat the specific multipliers as directional.
| Company | What they did | Reported result |
|---|---|---|
| Discovered (agency, B2B SaaS client) | Fixed schema/technical issues; published 66 answer-first articles in one month vs. a usual 8–10 | AI-referred trials rose 6x in 7 weeks |
| Apollo.io (in-house) | Built a genuine, disclosed brand subreddit (r/UseApolloIO) to correct outdated info LLMs cited | 63% citation rate on AI awareness prompts |
| Broworks (Webflow agency) | FAQ/Article/Organization schema, comparison tables, answer-first structure, sub-2s page loads | 10% of organic traffic from LLMs; 27% of those sessions became qualified leads |
| Intercore Technologies (agency, law firm) | Rewrote 50 pages answer-first; legal-entity schema; off-site presence | 68% AI visibility; $2.34M attributed revenue in 6 months |
The sequence repeats across all four — technical/schema cleanup, answer-first restructure, off-site presence — and each step maps to a Princeton finding.
⚠️ Worth flagging, not replicating. Part of Discovered’s lift reportedly came from posting in subreddits via aged accounts designed to read as ordinary members — materially different from Apollo’s disclosed approach. Reddit’s user agreement prohibits inauthentic engagement, and undisclosed commercial influence runs into FTC endorsement rules. It may have contributed to the numbers; it isn’t a checklist item. Apollo got comparable lift without the risk.
The technical work, condensed
- Unblock AI crawlers. Check
robots.txt:GPTBot,OAI-SearchBot,PerplexityBot,ClaudeBot,Google-Extendedmust not be disallowed. Verify against the operators’ own docs — OpenAI, Anthropic, Perplexity — user-agent strings change. ChatGPT search retrieves heavily via Bing’s index, so submit to Bing Webmaster Tools. - Lead with the direct answer. Self-contained answer in the first ~60–100 words of every priority page; depth below.
- Add structured data. FAQPage, Article, Organization, HowTo schema from schema.org.
- Fact density over adjective density. Specific, sourced numbers get extracted and cited; unsourced claims are invisible. (Direction supported by Princeton; be skeptical of precise ratios like “one statistic per 100 words.”)
- Track citations monthly. Ask ChatGPT, Perplexity, and Gemini your ten highest-intent buyer questions; log who gets cited. Traffic and conversions follow citations by weeks.
The prompt library: six specifications with acceptance criteria built in
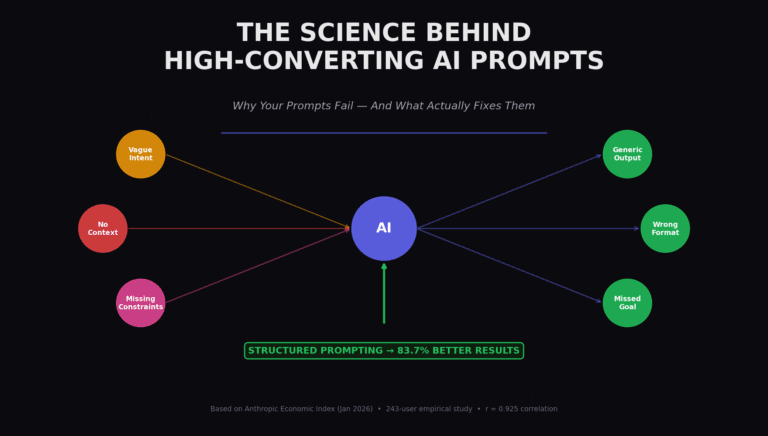
The standard that separates production prompts from demos isn’t clever phrasing — it’s checkability designed into the output format. A prompt whose only quality gate is “a human reads it carefully” is under-specified: the human is doing the work, and the model is a plausible-sounding draft generator. Each prompt below therefore defines acceptance criteria — conditions the output itself must satisfy to be valid — so checking takes seconds and can be delegated.
Prompt 1 — AEO page audit (Princeton GEO findings; Adobe citation-readability data)
Act as an AEO auditor. Full page text:[PASTE PAGE TEXT]Target buyer question: [QUESTION]Tasks:1. Does the first 100 words contain a direct, self-contained answer a model could quote verbatim? If not, write one.2. List every factual claim lacking a specific number, named source, or date. Flag each "unverifiable as written."3. Propose 3–5 FAQ entries (with FAQPage schema) for buyer questions the page answers nowhere.4. Recommend structured data types this page should carry.Output: a prioritized fix list ranked by expected citation impact,one line of reasoning per item.Acceptance criteria: (a) Paste the proposed answer-first paragraph into an AI assistant as a standalone query — it must answer the target question without the surrounding page, or the rewrite fails. (b) Every “unverifiable” flag must correspond to an actual sentence in the pasted text — spot-check three; models occasionally flag claims that were never there.
Why it works: Princeton measured up to +40% visibility from statistics, quotes, and citations; Adobe found blogs, guides, and FAQs have the highest AI citation readability of any content type.
Prompt 2 — Behavioral segmentation from support transcripts (McKinsey workflow-redesign finding)
Here are [N] anonymized support tickets:[PASTE, with ticket IDs]Cluster into behavioral segments — defined by what customers are trying toaccomplish and where they get stuck — not demographics.For EACH segment, output exactly this table:| Segment name | Job to be done (one sentence) | Friction (two verbatimticket quotes WITH IDs) | Segment size (count) | Oversight class(human-only / AI-with-review / AI-light-oversight) |Rules:- A segment without two verbatim quotes from real ticket IDs is not a segment. Output it under "INSUFFICIENT EVIDENCE" instead.- Do not force ambiguous tickets into clusters. List them under "UNCLUSTERED" with the reason.Acceptance criteria: pick two segments at random and confirm every quoted ticket exists verbatim in the input. If any doesn’t, discard the entire run — hallucinated evidence means the cluster boundaries are unreliable too. The “INSUFFICIENT EVIDENCE” and “UNCLUSTERED” buckets are features: they make the model’s uncertainty visible instead of laundering it into confident-sounding groups.
Why it works: pattern-matching at volume with an auditable output schema — the “repeatable, checkable” profile that separates McKinsey’s high performers from everyone else.
Prompt 3 — Stalled-deal diagnosis (sales-cycle ROI)
Here are call notes and email summaries for a stalled deal:[PASTE]Output exactly:1. LIKELY BLOCKER — three sentences maximum.2. LAST COMMITMENT — the last concrete commitment the prospect made, with date.3. OPEN QUESTIONS — every unanswered question/objection in their own words.4. NEXT ACTION — the single highest-leverage action, and who should take it.Rules: if the notes don't support a conclusion, write "INSUFFICIENT SIGNAL."Never recommend a step the notes don't justify.Acceptance criteria: this prompt is designed to be scored, not just read. Quarterly, compare its recommended next actions against what actually closed in your CRM. Keep using it only if its recommendations correlate with deals that moved. A prompt you never score is one you’re trusting on faith — and “INSUFFICIENT SIGNAL” appearing often is itself a finding about your call-note quality.
Why it works: judgment-adjacent but validatable against outcomes — the only honest way to use a model near a revenue decision.
Prompt 4 — Competitive claims comparison (narrow-scope principle)
Here are my positioning page and [COMPETITOR]'s equivalent page:[PASTE BOTH, labeled OURS / THEIRS]Extract specific, falsifiable claims only: pricing, features, integrations,certifications, quantified outcomes.Output a table:| Claim | Side (ours/theirs/both) | Verbatim quote from source | Section| Evidence cited in source (yes/no) |Rules: no row without a verbatim quote. No tone analysis, no "brand voice"commentary. If a claim can't be quoted, it doesn't exist.Acceptance criteria: the quote requirement makes hallucination self-evident — spot-check three rows against the source text. Pay special attention to claims attributed to the competitor: this is where models most often import training-data beliefs instead of reading what you pasted. If any quote is missing from the source, discard the run.
Why it works: narrow, factual, checkable — and it produces the comparison tables that both Princeton and the Broworks case found AI engines like to cite.
Prompt 5 — Workflow-mapping and automation triage (McKinsey’s #1 predictor)
I run [BUSINESS/ROLE]. Here is a step-by-step description of how we handle[TASK], including who's involved and where it slows down or gets expensive:[PASTE]Classify each step:(1) JUDGMENT — needs a human's call(2) PATTERN — repeatable matching; AI with light review(3) AUTOMATABLE — could run with <20% oversight given the right checksThen propose a phased roadmap: what to automate first, what evidence wouldtell us it's working, what breaks if we move too fast.Acceptance criteria: before acting on the roadmap, the person who actually does the work must review the process map. Models classify the process you described, not the one that exists — the two routinely diverge. Budget that review as step zero of the roadmap, not as an afterthought; it’s the cheapest quality gate in the entire exercise. If the reviewer says “that’s not how it works,” the roadmap is fiction however plausible it reads.
Why it works: workflow redesign is the strongest predictor McKinsey measured of EBIT impact showing up at all.
Prompt 6 — AI citation tracking (Adobe/HubSpot: citations lead, revenue follows)
My brand: [BRAND]. My 10 highest-intent buyer questions:[LIST]For each question I will paste answers returned by ChatGPT, Perplexity, Gemini.Build a tracking table:| Question | Brands cited | Me cited? (yes/no) | Sources cited instead |What those pages have that mine lacks (direct answer / statistics / schema /quotes / freshness) |End with: the two highest-leverage changes I could make this month to raisemy citation rate.Acceptance criteria: AI answers are non-deterministic and personalized, so a single snapshot misleads. Log results in a spreadsheet monthly; the trend across months is the signal, any single month is noise. Note also what this prompt can’t tell you: zero-click buyers who never visit your site at all (see the Adobe caveats above).
Why it works: turns “are we visible in AI search?” from a vibe into a monthly metric with named competitors.
Prioritizing AI prompt work: one framework, said once
The highest-value work sits where a task is high-frequency, currently expensive with a human, and checkable — where “correct” can be defined clearly enough to audit.
| Function | What the prompt does | Why it works |
|---|---|---|
| Content & AEO | Audit pages for answer-first structure, schema, unanswered buyer questions | Maps directly to Princeton + the case-study pattern |
| Customer research | Cluster support transcripts into behavioral segments | Pattern-matching at volume, auditable output |
| Sales ops | Flag stalled deals, summarize the blocker | Validatable against what actually closes |
| Competitive intel | Compare messaging on falsifiable claims only | Narrow, factual, slow for a human to do by hand |
| Operations | Map a process; classify steps by oversight needed | McKinsey’s strongest predictor of EBIT impact |
Where teams go wrong — and both MIT and McKinsey point at the same root cause: reaching for a general-purpose tool to do a specific job, then judging “AI ROI” by that mismatch. A chatbot asked to “write a blog post about X” produces something readable and undifferentiated; if that’s the whole strategy, traffic can rise while conversions fall, because the output carries no information a competitor’s AI-generated post doesn’t also carry. Princeton’s finding that keyword stuffing hurts more than it helps is the academic version of the same warning: content written for a crawler rather than a reader is penalized by generative engines, not rewarded. The fix isn’t better phrasing; it’s narrower scope. Use the prompt for analysis and pattern-matching; keep humans on the parts requiring real differentiation — the actual writing, the actual client relationship.
FAQ
Do AI prompts actually deliver measurable ROI, or is it hype?
Both, simultaneously. McKinsey found only ~6% of organizations see real bottom-line impact — skepticism about the average is warranted. But the same survey, plus the case studies and Princeton’s controlled experiments, shows narrowly scoped, workflow-integrated work produces verifiable results. The average outcome is weak; the outcome for teams that scope correctly is not.
Why do most enterprise AI pilots fail to reach production?
MIT points to a “learning gap”: generic tools don’t adapt to a specific company’s workflow, so they demo well and stall in daily use. McKinsey adds that workflow redesign — not the tool — is the strongest predictor of whether a pilot produces value.
Is it safe to “seed” Reddit or other platforms to influence AI citations?
Real, disclosed brand accounts participating honestly — as Apollo.io did — are legitimate marketing. Undisclosed or “aged” accounts simulating organic recommendations violate platform terms and can run into FTC endorsement rules. It’s a legal risk, not a style choice.
How long does AEO take to show results?
Nobody knows precisely; distrust exact figures. Based on Tier B practitioner reports, retrieval-based engines (ChatGPT search, Perplexity, Google AI Overviews) typically reflect content changes within weeks — they index the live web. Influencing base models’ parametric memory takes months to years and isn’t directly controllable. There is no controlled study establishing a window; treat “4–8 weeks” claims as anecdote. This uncertainty is exactly why Prompt 6 is the right leading metric: it tells you what’s happening for your site rather than what should happen on average.
What’s a reasonable first step?
One narrow, high-frequency, currently expensive task — not a company-wide initiative. Define what a correct output looks like before you start. Run it for 30 days against the human baseline. That single discipline is the biggest differentiator in the data above.
Action checklist
- Pick one narrow, high-frequency, currently expensive workflow — not a company-wide “AI initiative”
- Define acceptance criteria in writing before building anything
- Check
robots.txt(AI crawlers unblocked); submit sitemap to Bing Webmaster Tools - Schema/technical audit on highest-intent pages before writing new content
- Rewrite key pages answer-first: direct, sourced answer in the first 60–100 words
- Replace adjectives with sourced specifics (direction supported by Princeton; ignore precise ratios)
- Track AI citations monthly — traffic and conversions follow with a lag
- Build any off-site presence as a real, disclosed account — never a sockpuppet
- Redesign the workflow around the AI step, not the reverse
Where this is heading
Single-shot prompts are giving way to multi-step, tool-using agents — McKinsey found 62% of organizations already experimenting with agentic AI. Adobe’s August 2026 report adds a sharper nuance: AI engines cite structured, informational content (blogs, guides, FAQs, support pages) far more readily than dynamic flows (booking, checkout, account creation). The businesses that win the next two years will have machine-citable public content and machine-delegable internal workflows — two sides of the same skill.
What won’t change is the underlying discipline: take a real business problem, break it into steps a model can execute and a human can verify in seconds, and measure whether it moved a number that mattered.
A closing note, applied to this article
If the data above is right, you don’t need a library of 500 prompts. You need one — scoped to your most expensive, most frequent, most checkable workflow — run for 30 days against a human baseline. Take what you can verify from this page; ignore what you can’t. That standard applies to us too: the prompt library at BestPrompt.art is affiliated with this article’s publisher, which is why every statistic above links to a source we don’t control, so you can check our claims independently.
Sources
Primary research
- McKinsey, The State of AI: Global Survey 2025
- McKinsey, How Organizations Are Rewiring to Capture Value
- MIT NANDA, The GenAI Divide: State of AI in Business 2025 — Forbes coverage · methodology caveat
- Aggarwal et al., GEO: Generative Engine Optimization, KDD 2024
- Adobe Digital Insights, AI Traffic Trends Report, August 2026 (PDF) · Digital Commerce 360 coverage
Case studies & secondary reporting (Tiers B–C)
Implementation & official documentation
- Google Search Central, structured data introduction · schema.org
- Bing Webmaster Tools
- OpenAI crawler docs · Anthropic ClaudeBot docs · Perplexity bot docs
- FTC, Endorsements, Influencers & Reviews
People worth following
- Ethan Mollick — Wharton; One Useful Thing is the most practically grounded writing on organizational AI adoption.
- Andrew Ng — the Prompt Engineering for LLMs course at DeepLearning.AI remains the best free technical foundation.
- Pranjal Aggarwal & the Princeton/Georgia Tech GEO team — the only controlled academic study of AI citation optimization; the paper is readable.
- MIT Project NANDA — the least-hyped enterprise AI data available.
- Wil Reynolds / Seer Interactive — the most rigorous published measurement of AI-referred traffic in the wild.
- Lily Ray — technically rigorous on how traditional SEO and AI search visibility interact.
- Rand Fishkin / SparkToro — the leading public research on zero-click behavior.
- Aleyda Solís (Orainti · @aleyda) — rigorous practitioner publishing on technical AEO.
- Danny Goodwin / Search Engine Land — the most reliable filter separating AEO evidence from AEO marketing.
Disclosure: this article links to BestPrompt.art, which is affiliated with its publisher. Known limitations: Adobe figures are U.S. retail only; the case-study table is vendor self-reported (labeled as such); the prompt library has not been benchmarked against any external evaluation — judge it by running it, which is the standard this article asks you to apply to everything else.