73% of AI Implementations Fail in Week Three. Here’s What the Other 27% Are Doing Differently.


Beyond the 95%: What Enterprise AI Deployments That Actually Work Have in Common
Updated September 2026. Every statistic below is sourced and linked at the end — including the sources that disagree with this article’s premise.
The “95% of enterprise AI pilots fail” statistic is directionally useful and technically shaky. The pattern underneath it is neither.
Ask ten companies why their AI pilot never left the demo stage, and most will blame the model — not smart enough, hallucinated too often, the vendor overpromised. Ask the handful whose pilots became production systems that move real numbers, and you get a different answer: what they built around the model. A way to specify what “good” looks like, test for it, and keep testing after launch.
That gap has a name and — sort of — data behind it. This piece is about both.
The number everyone cites, and its limits
In July 2025, MIT Media Lab’s Project NANDA published [The GenAI Divide: State of AI in Business 2025](https://nanda.media.mit.edu/ai_report_2025.pdf). The methodology, per the report itself: a review of 300+ publicly disclosed AI initiatives, structured interviews across 52 organizations, and survey responses from 153 senior leaders, collected January–June 2025. The findings, roughly:
| Stage (task-specific / enterprise GenAI systems) | Share of organizations |
|---|---|
| Evaluated such a system | ~60% |
| Reached pilot stage | ~20% |
| Reached production with measurable P&L impact | ~5% |
General-purpose tools (ChatGPT, Copilot) are far more widely adopted — but the report argues that they mostly enhance individual productivity rather than P&L performance. It estimates $30–40B in enterprise GenAI spend, names the core failure mode a “learning gap” (tools that can’t retain feedback or adapt to how an organization actually works), and finds vendor-built, workflow-integrated tools succeeded at roughly twice the rate of in-house builds.
Now the part most coverage skips. The report’s authors label it preliminary findings and describe its figures as “directionally accurate” — anonymized interview data, not audited deployment counts. And the statistic mutated badly as it traveled: Fortune’s August 18, 2025 story ran “95% of generative AI pilots are failing”; some secondary coverage described “150 executive interviews and a 350-employee survey,” numbers that appear nowhere in the report’s methodology section. Wharton’s Ethan Mollick called the headline a myth in need of debunking; Kevin Werbach’s analysis (popularized via Futuriom) argues the “95%” is an illogical leap from a nested subset — 5% of the 20% who piloted task-specific tools, out of the 60% who evaluated them — and notes NANDA sits close to agentic-protocol vendors (Google, Anthropic) with an interest in the “buy, don’t build” conclusion. Nathaniel Whittemore of Superintelligent reached a similar verdict, and Penn Today’s roundup captures why the report spooked markets anyway.
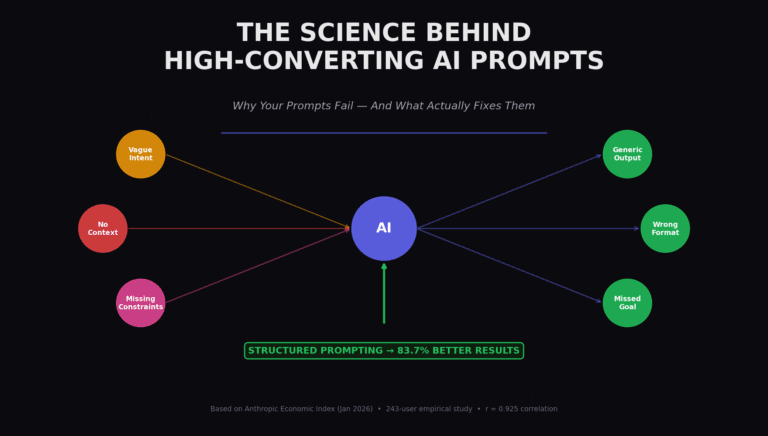
So treat the precise percentage the way the authors do: as direction, not census. What survives scrutiny is the qualitative pattern, which independent evidence broadly supports — including surveys showing buyers satisfied with general-purpose AI tools. The apparent contradiction dissolves once you separate adoption from transformation: copilots are liked; custom, workflow-embedded systems are the ones that die in pilot; and they’re the only kind that can move a P&L line. The winners in NANDA’s sample weren’t running better models. They were running a documented, versioned, tested process for turning a business requirement into a working system — and their tools could learn from feedback instead of resetting to zero every session.
What “prompt engineering” actually means here
Worth untangling, because most coverage blurs it. Prompt engineering, strictly, is designing the natural-language instructions given to a language model — the system prompt behind a chatbot or search tool. Marriott’s AI search is prompt engineering. Klarna’s assistant is prompt engineering.
Mastercard’s fraud-scoring models and Shell’s predictive maintenance aren’t — they’re machine learning trained on structured transaction and sensor data, only partly touching generative components. What all six examples below share is the older, broader discipline underneath: define exactly what the system must and must not do, build a way to measure whether it does it, version every change, and never treat a first working version as finished. Prompt engineering is one visible expression of that discipline, the one that appears when the interface is natural language. The discipline itself is why these deployments avoided the ditch — and it predates the ChatGPT era by years.
Six deployments, checked against primary sources
Verified against company newsrooms and official releases as of September 2026. Where a company hasn’t published an isolated ROI figure, that’s stated plainly — the absence of a number is itself informative.
Hospitality: structured data first, chatbot second
Marriott launched Ask Bonvoy in beta on June 16, 2026 — conversational trip search across ~10,000 properties in 146 countries, initially U.S. English for a subset of Bonvoy members, with a planned global rollout toward 283 million members later in 2026. Responses are grounded exclusively in Marriott’s own verified property data rather than open web content — a deliberate constraint, not an afterthought. Marriott has published no standalone revenue figure for the tool, and that’s a good sign: revenue management has dozens of moving parts, and honest attribution won’t isolate one variable and claim credit for a RevPAR swing. Treat any article that hands you a precise percentage here with suspicion.
Financial services: probability, not a yes/no switch
HSBC’s Dynamic Risk Assessment, built on Google Cloud’s AML AI (2023), identifies several times more true suspicious activity than HSBC’s prior rules-based approach while cutting false-positive alert volume by more than half — figures HSBC and Google still cite today.
Mastercard’s Decision Intelligence Pro (February 2024) scans a trillion data points per transaction and, in Mastercard’s own modeling, lifts fraud detection ~20% on average (up to 300% in some cases) and cuts false positives by more than 85%; a May 2024 companion doubled compromised-card detection rates. In March 2026 Mastercard went further, announcing a foundation model — a “large tabular model” trained on billions of anonymized transactions with Nvidia and Databricks, positioned as an insights engine across product lines rather than one use case at a time (PYMNTS coverage). Every one of those performance figures is vendor-reported. The architecture is the reliable part: score every transaction as a probability against a threshold the business tunes — never a binary call.
Healthcare: a narrow prediction, a hard-coded human response
Kaiser Permanente’s Advance Alert Monitor scans hospitalized patients’ electronic health data hourly and flags elevated risk of sudden clinical decline, routing the signal to a specialized nursing team before an emergency. Kaiser’s published research links the program to several hundred prevented deaths a year, with peer-reviewed evaluations finding lower mortality among monitored patients meaningfully. Two things matter here: the model never makes a clinical decision — it routes to a human, every time — and the program’s Northern California origins date to around 2013, refined years before “AI” was a boardroom buzzword. Good specification discipline isn’t a post-2023 invention; generative AI just made it accessible to teams without a data science department.
Retail: the case study everyone cites half of
Klarna’s OpenAI-built assistant handled ~2.3 million conversations in its first month after February 2024 — two-thirds of customer service volume, work Klarna priced at 700 full-time agents, with resolution under two minutes and repeat inquiries down 25%. Most articles stop there.
The omitted part: by the end of 2024, Klarna’s workforce had fallen from roughly 5,500 to about 3,800 — a ~3,500 target was floated for 2025 — mostly through attrition rather than layoffs. In May 2025, CEO Sebastian Siemiatkowski told Bloomberg the company had over-rotated: cost had been “a too predominant evaluation factor,” quality had suffered, and Klarna was reopening human hiring through a flexible, “Uber-type” tier (CX Dive’s report has the details). Klarna disputes the “reversal” framing — it notes the assistant now covers work equivalent to 800+ FTEs, that several thousand outsourced agents always remained, and that the human pilot started with two agents (its statement, via Forbes). Fair enough — and the correction is still the useful data point: measure resolution quality, not headcount avoided, or you discover the gap the hard way. The boundary between the AI tier and the human tier is a design decision, not a one-time cut.
Energy and industrial: scale is the verifiable story
Shell and C3 AI extended their partnership in a multi-year agreement on June 4, 2026, moving 13,000+ monitored pieces of equipment from anomaly detection into agent-based root cause analysis, on C3’s Agentic AI Platform and Azure. C3 president Stephen Ehikian’s claim of “hundreds of millions of dollars in economic value” is a vendor figure, not an audited one — weigh it accordingly. The verifiable details are the guardrails and the scale: the agentic tools are advisory in this phase, humans still approve remediation, and a deployment this size is extraordinary for industrial maintenance on a partnership dating to 2018. No independently audited savings figure exists for the program.
Telecom: a narrow code-generation task, not open-ended chat
Vodafone and Zinkworks announced Rapid RIC on October 21, 2025 — a platform, expected fully operational in early 2026, that turns a drag-and-drop visual specification into working network software (rApps). The stated goal: a 60–70% cut in development and launch time, from months to ~3–4 weeks, with Chief Network Officer Alberto Ripepi and Zinkworks CEO Paul Madden both on record. The first rApps target energy savings on unused connections and ML-based coverage tuning. Note what’s not here: open conversation. The “prompt” is a structured spec validated by a simulator before deployment — a large part of why the task is tractable at telecom-grade reliability requirements.
The pattern across all six
| Industry | Verified example | What’s actually driving it | Common failure mode |
|---|---|---|---|
| Hospitality | Marriott Ask Bonvoy (beta, June 2026) | Machine-readable inventory feeding a constrained language layer | Chatbot bolted onto messy inventory data, with nothing to check answers against |
| Financial services | HSBC × Google Cloud AML AI; Mastercard DI Pro | Models trained on the institution’s own history, scored against a tuned threshold | Treating fraud detection as binary instead of a probability the business calibrates |
| Healthcare | Kaiser Advance Alert Monitor | A narrow, well-defined prediction with a hard-coded human response protocol | Letting the model make the call instead of routing it to a clinician |
| Retail | Klarna’s assistant — and its 2025 recalibration | Deep integration into authenticated account data, not a bolt-on FAQ widget | Optimizing for headcount avoided instead of resolution quality |
| Energy | Shell × C3 AI predictive maintenance | Millions of sensor readings mapped to well-labeled historical failures | Predictive maintenance without the sensor and labeling infrastructure to train on |
| Telecom | Vodafone × Zinkworks Rapid RIC | A defined spec (an rApp) turned into code — not open-ended text | Asking a general-purpose model to write domain-critical software unconstrained |
The row the table can’t show: in five of six cases, a human still catches what the system gets wrong before it reaches a customer or a balance sheet. Klarna’s first eighteen months are the exception — and its 2025 course correction is the clearest available evidence for why the checkpoint matters.
What a well-specified system looks like in practice
Not a leaked prompt from any company above — an illustrative pattern for how constraint-based systems are typically structured:
ROLE: You are a [specific function], operating only within [defined scope].
CONTEXT: You will receive [exact data sources]. You have no access to anything outside this context.
CONSTRAINTS:
- Never [specific prohibited action].
- If confidence is below [threshold], escalate to a human instead of answering.
- Cite only information present in the provided context.
OUTPUT FORMAT: [structured format — JSON, a specific template]
EVAL: Versioned prompt. Current: [x.x]. Tested against [N] labeled examples.
Baseline accuracy: [%]. No deploy without re-running this set.
What the EVAL line catches, mechanically: a traveler asks a hotel-search assistant for “a family-friendly hotel near the beach with a kids’ club.” Without a constraint, the model matches “family-friendly” against loose amenity text and returns a property with a playground but no kids’ club — technically defensible, practically wrong. Add that exact query to the evaluation set with the correct answer labeled, and a one-off complaint becomes a permanent regression test: every future prompt version gets checked against it before deployment. That is the entire difference between a demo and a production system — one bad case, caught once, stays caught.
Tooling: compressed to what survives contact with 2026
Once a prompt matters to the business, it stops living in a chat window and starts living in a versioned repository with CI — the same rigor as code, because that’s what it now is. The vendor category forming around this (LLM observability and prompt management) is consolidating faster than any article can track: ClickHouse acquired Langfuse on January 16, 2026 alongside a $400M Series D, with both companies committing to keep the MIT license and self-hosting path unchanged; LangSmith remains the default for LangChain-based stacks. Don’t pick on features or price — the category will look different next quarter. Pick on one axis: does the tool make your evaluation results reproducible across model upgrades? Everything else is interface preference.
A 90-day plan with gates, not vibes
Generic playbooks fail because nothing is falsifiable. Each phase below ends in a deliverable and a pre-committed go/no-go rule.
Days 1–30 — One use case with a number attached. Something revenue, cost, time, or risk already gets tracked. Deliverable: the baseline recorded in writing, plus a one-page spec listing what the system must never do. Kill rule: no baseline, no pilot — you cannot prove improvement against a number you never wrote down.
Days 31–60 — Evaluation set before any “final” prompt. 50–100 real examples with labeled correct answers — not synthetic ones. Every prompt change versioned and re-run against the full set. Deliverables: prompt v0.x with measured accuracy against the baseline, and the escalation rule written down (confidence below threshold → human, no exceptions).
Days 61–90 — Limited rollout behind a human gate. A small group, weekly comparison against baseline. Expansion criteria committed before results arrive (e.g., accuracy at or above baseline, zero severity-1 misses in review, review time under N minutes per case). Rollback rule committed in the same document. Expand scope when the numbers hold — not when the demo looks good.
The bottom line
Strip away the contested percentage and the finding survives: the organizations whose AI deployments work aren’t running better models. They’re running systems that can retain feedback and adapt to how their own organization works — specified tightly, measured honestly, versioned relentlessly, and watched by a human at every boundary that matters. The model was never the hard part. The discipline around it was, and it’s learnable in about 90 days.
Where every claim comes from
The MIT study and the debate around it
- The GenAI Divide: State of AI in Business 2025 (report PDF) — Project NANDA, July 2025
- Fortune via Yahoo Finance and Forbes (Jason Snyder) — coverage that amplified the 95% figure
- Ethan Mollick, Futuriom on Kevin Werbach’s critique, Penn Today roundup — the pushback
Case studies (primary sources first)
- Marriott: Ask Bonvoy launch release
- HSBC × Google Cloud: AML AI announcement
- Mastercard: Decision Intelligence Pro, May 2024 release, 2026 foundation model, PYMNTS
- Kaiser Permanente: Division of Research program overview
- Klarna: February 2024 release, eMarketer on the May 2025 reversal, CX Dive, Klarna’s own framing via Forbes
- Shell × C3 AI: June 4, 2026 release
- Vodafone × Zinkworks: newsroom announcement
Tooling
Scope note: where figures come from a company’s own modeling or a vendor, the text says so inline. That is a feature, not a hedge — in this field, the source of a number matters more than its precision.