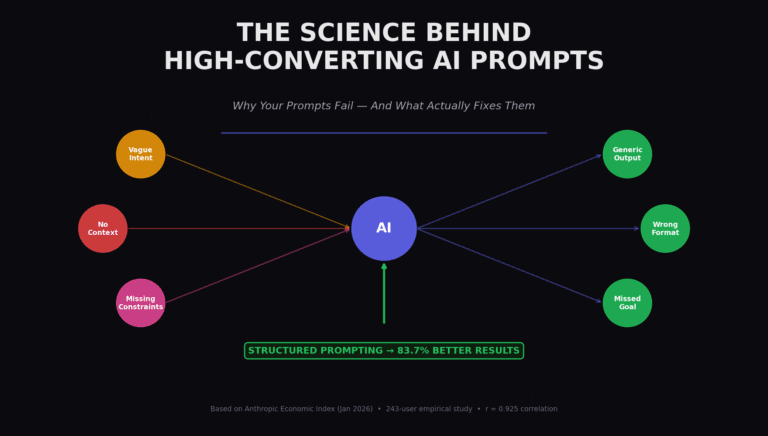
A “ChatGPT prompt success story” is usually defined as one perfectly worded prompt that single-handedly fixed a business problem. That’s the marketing definition. After spending a week pulling apart the company case studies that actually exist — OpenAI’s own customer files, SEC filings, Bloomberg, a Harvard working paper — the operational definition looks different: almost none of these stories are about a single clever prompt. They’re about someone testing a prompt against real cases, watching it fail in a specific way, and fixing that one thing before they told anyone it worked.
I started this piece trying to hit 25, because that’s the number every other version of this article promises. I got to 21 verified ones — named person, named company, a working link to the original source — and then I ran out of real ones. Four more existed only in listicles that reused the same uncredited numbers as each other. So this is 21, and the four I cut are arguably the most useful part of the lesson: that’s roughly how much of this genre is recycled invention.
Quick note on method, since the rest of this is only useful if you trust where it came from: every case below is sourced to a company’s own published account, a named executive on record, a regulatory filing, or peer-reviewed research — linked at the point of use, not bundled into a bibliography at the bottom. Where a number is a company’s own estimate rather than an audited figure, I’ve said so in the sentence, not hidden it in a footnote. Two cases (Klarna, the Harvard/BCG study) are included specifically because they complicate the “AI just works” version of this story; leaving them out would have made the list more flattering and less true.
| Case | Sector | Verified outcome | Source |
|---|---|---|---|
| 1. Sharp & Sharp Seed Farm | Agriculture | 54-year paper ledger made searchable by voice | OpenAI |
| 2. The Original Tamale Co. (Christian) | Food / retail | Locator tool shipped same afternoon, zero code experience | OpenAI |
| 3. The Original Tamale Co. (Xochitl) | Food / retail | Bilingual leadership communication, second-language confidence | OpenAI |
| 4. Reno Salvage | Industrial | 1,000-item part catalog built in one afternoon | OpenAI |
| 5. Edith Mwiti, freelancer | Freelance services | Self-reported: Upwork client landed in 3 hours | Medium |
| 6. Notion | Software | Cross-platform feature: ~2 weeks → 3–4 hours | OpenAI |
| 7. Nextdoor | Software | Three-team feature shipped solo by one engineer | OpenAI |
| 8. Datadog | Software | ~22% of past incidents flagged in replay test | OpenAI |
| 9. Indeed | HR tech | +20% applications, +13% downstream hires (A/B test) | OpenAI |
| 10. Lowe’s | Retail | Conversion rate more than doubled on assisted sessions | OpenAI |
| 11. Intercom | SaaS / support | Model migration validated and shipped in 48 hours | OpenAI |
| 12. BBVA | Banking | 20,000+ employee-built assistants, 2.8 hrs/week saved | OpenAI |
| 13. BBVA Peru | Banking | Query handling: 7.5 min → ~1 min | OpenAI |
| 14. LSEG | Financial data | Release cycles: 3–6 months → 2 weeks | OpenAI |
| 15. Preply | Edtech | Per-lesson AI feedback at marketplace scale | OpenAI |
| 16. Singular Bank | Private banking | 60–90 minutes/day reclaimed per banker | OpenAI |
| 17. Boston Children’s Hospital | Healthcare | 40+ rare-disease cases newly diagnosed | OpenAI |
| 18. Travelers Insurance | Insurance | 85–90% of claims self-completed via AI assistant | OpenAI |
| 19. Klarna | Fintech | 2024 high, then a public 2025 walk-back — both verified | Bloomberg |
| 20. Harvard/MIT/Wharton/BCG study | Research | +40% quality, +25% speed — and a sharp failure mode | HBS |
| 21. Duolingo | Edtech | Shipped only after GPT-3 was judged not good enough | OpenAI |
These are the cases I trust most, because there’s no PR team between the person and the claim. Most of them never wrote a “prompt” in the engineering sense — they just described a problem in plain language until the answer was usable.
Rachael Sharp is taking over Sharp & Sharp Certified Seed, her family’s farm in Allendale, South Carolina, and inheriting her father’s handwritten planting records going back to 1971. Her own description of the stack: “It’s so much data, it almost scares you away.” Instead of leaving it in notebooks, she had ChatGPT turn the archive into something she could query on demand — past yields, planting dates, what worked on which field, in seconds rather than a drawer search.
The part that’s easy to miss: she’s not typing this at a desk. Riding the combine or walking a soybean field, she logs loads and checks details by voice, and photographs a stressed-looking crop to ask what’s wrong with it on the spot. South Carolina has gone from over 200 certified seed farms to seven. Acting on decades of inherited judgment without breaking stride to look something up is, in that context, a survival trait, not a convenience.
“Before, I would wonder, where can I get this, who can help me with that. And now it’s like, okay, I can do this.”— Don Sharp, Rachael’s father, on his daughter’s use of ChatGPT
The Original Tamale Co. started in a garage and is now a third-generation operation working hundreds of farmers markets across California. Customers kept losing track of which market the family would be at on a given day. Christian Ortega, who handles marketing and operations, had never written a line of code. He described the tool he wanted — searchable by ZIP code, near-me lookup, an editable list of markets — and had a working version live on the website the same afternoon.
The detail worth noting for anyone tempted to write this off as a toy demo: it’s a real, functioning map-and-search tool with a maintainable data structure, not a static page. Nobody had to be hired, scheduled, or waited on for a feature that, written from scratch, would normally involve a developer and a few days minimum.
“I had the idea, made it that same afternoon, and put it on the website. I didn’t need to wait on anyone. I could just do it.”— Christian Ortega, The Original Tamale Co.
Same company, a completely different use of the same tool. Xochitl Ortega co-runs the family business and does it in a second language. Addressing employees, handling a tense moment with a vendor, speaking publicly on behalf of the company — all of it carried the extra weight of translating instinct into English in real time. Her approach: start in Spanish, work the tone and phrasing with ChatGPT until it actually sounds like her, not like a translation app.
What changed wasn’t her judgment. It was the gap between knowing what to say and being able to say it without hesitation in the room. That’s a narrower, less flashy use of the tool than a coded feature, and it’s also the one most likely to apply directly to a reader running a business in a language that isn’t their first.
“I feel like I just went to university. Like I went to a seminar, and now I can speak to anyone — from the person who cleans, to the CEO of a company. I’m confident.”— Xochitl Ortega, The Original Tamale Co.
Reno Salvage has run for 86 years on the kind of institutional memory that lives in one or two people’s heads. Richard Lane manages the yard, and his daily job is closer to triage than planning: a plasma cutting table fails mid-shift, a customer needs a spec nobody on duty has memorized, downtime stacks up by the hour. When the cutter broke, instead of waiting days for a technician, he described the fault to ChatGPT and got a troubleshooting step that fixed it on the spot.
The bigger fix was a part-numbering system for more than a thousand products that the yard had put off for years because doing it by hand looked like weeks of work. Lane built it in an afternoon, organized so the crew could actually remember the scheme rather than just look it up. He’s also used it to draft an investor-facing business plan for his own welding venture and to settle a real metallurgy disagreement among welders about rod storage — the kind of question that used to mean calling around.
“I don’t necessarily see AI as the answer to all the questions. It’s more like a partner helping you find answers in yourself.”— Richard Lane, Reno Salvage
This is the one case here that’s self-reported rather than independently verified, and it stays in the list because it’s specific enough to check and ordinary enough to be believable. Freelance writer Edith Mwiti had been losing proposals into the void for months — generic pitches, no clear positioning. She fed ChatGPT her actual profile and asked for a rewrite around concrete keywords, then stopped using template proposals entirely and started pasting the full job post in and asking for a response built around that client’s specific language.
For balance: a separate, anonymously published account of the same tactic, tested across ten Upwork proposals, found the opposite when the writer skipped the personalizing step — replies came only from the proposals where they added a real, specific detail about their own work. Both accounts agree on the actual mechanism: generic prompts produce generic proposals that clients can smell from the subject line. The technique that worked wasn’t “use ChatGPT for proposals.” It was “paste in the real job post and refuse to let it write something five other freelancers could have sent.”
At three software companies, the actual unit of work shifted from “write the function” to “describe the result precisely enough that something else can write the function.” That distinction is the closest thing to a transferable prompting skill in this entire list — the prompt frameworks in our template library follow roughly the same logic: specificity does the work, not cleverness.
Ryan Nystrom leads AI Product Engineering at Notion. When a voice-input feature existed on mobile but not on web or desktop, the historical cost of porting it was real: mobile, frontend, and backend teams, roughly two weeks of coordinated effort. Nystrom pointed OpenAI’s coding agent Codex at the mobile codebase, described how the feature needed to look and behave on web, and gave it a way to verify its own output. It returned a complete first cut that matched Notion’s existing code conventions closely enough to ship the next day.
His own framing of what changed: “I’ve almost found myself spending a lot more time writing these spec documents that I can hand to Codex and let it work on. Honestly, I don’t really write code by hand anymore.” That’s not a productivity hack, it’s a different job description for the same title.
Cory Dolphin, head of engineering at Nextdoor, named the shift directly: “away from iteratively prompting an agent, and towards outcome engineering, where engineers start to think about the result they want to see and work with an agent to engineer that result.” On Nextdoor’s Opportunity Alerts feature, an engineer wanted service providers shown on a map — historically a request that required mobile, frontend, and backend engineering to coordinate, and one that might never have cleared the backlog at all. With Codex, one person built it end to end.
Dolphin’s team also leans on the same tooling for the unglamorous part of the job: debugging Kubernetes pods that won’t start and tracing race conditions in Rust databases that are genuinely hard to reproduce by hand. The honest line from his own account is worth keeping: “a lot of the team are addicted to it,” which is a different kind of admission than a press release usually makes.
This is the case I’d point a skeptic to first, because Datadog didn’t take the result on faith. Brad Carter’s team built a replay harness: they pulled pull requests that had already caused real production incidents, ran Codex against each one exactly as if it were the original reviewer, and then asked the engineers who’d lived through those incidents whether the feedback would have changed anything.
The result, stated plainly rather than rounded up for effect: Codex flagged something useful in roughly 22% of the incidents tested — more than any other tool Datadog evaluated, and notably, on pull requests that had already passed human review. More than 1,000 of Datadog’s engineers now use it regularly, and the internal signal isn’t a dashboard metric, it’s engineers posting in Slack when a comment changed how they thought about a problem.
What this looks like once the mistakes have a dollar value
At consumer scale, in a regulated industry, or in front of a patient, “good enough on the first try” isn’t an option. Every one of these ten cases ran some form of A/B test, replay, or staged rollout before anyone called it a success — that discipline, more than any wording trick, is the actual differentiator.
The technique was naming the why, not just the what
Indeed’s “Invite to Apply” feature already matched job seekers to roles. What it didn’t do well was explain why a given match made sense, and that gap mattered: people apply more often, and more successfully, to jobs they understand. Using few-shot prompting — showing the model worked examples of good explanations rather than just instructing it to “explain the match” — Indeed’s team got GPT to generate that context at scale, then fine-tuned a smaller model to deliver the same quality using 60% fewer tokens once the approach was proven.
In Indeed’s own A/B test against the prior version, the GPT-powered explanations produced a 20% increase in started applications and a 13% improvement further down the funnel, in interviews and hires specifically — not just clicks. “Regardless of how good our matching is, explainability is key to any successful recommendation system,” said CEO Chris Hyams.
The associate tool that almost shipped without voice input
Lowe’s built two assistants on the same foundation: Mylow for customers on the website, and Mylow Companion for the 1,700-plus stores’ associates. The customer-facing version alone more than doubled conversion among shoppers who used it, and in-store customer satisfaction scores rose roughly 200 basis points on assisted interactions. “What makes Mylow powerful is it understands int