Updated June 2026 · Sources linked throughout, primary documents preferred
When Anthropic’s own growth marketer wanted proof that prompting moves a real number, he didn’t reach for a clever sentence. He typed /rsa into Claude Code — a slash command he’d built himself — and watched it pull campaign data, cross-reference three brand-voice rules he’d written down once, and hand back fifteen headlines and four descriptions packaged into a CSV ready to upload. Anthropic’s own write-up puts the before-and-after in plain numbers: ad copy that took two hours now takes fifteen minutes, and the volume of variants tested per cycle went up roughly tenfold. None of that came from one brilliant prompt. It came from a command, a handful of reusable skill files, and a memory system that remembers which headlines already flopped.
That distinction is the whole article, really. Most of what gets published under the banner of “AI prompt wins” is one of two things: a case study with a number but no prompt in it, or a prompt with no number attached. The companies below published both — the actual mechanism and the figure it produced — which is rarer than it should be. Ten are listed here, each with a link back to where the claim actually lives, so you can go check it yourself instead of taking a blog’s word for it.
Back to Anthropic’s own marketing team, because the detail matters more than the headline number. The /rsa command doesn’t hand the whole job to one prompt. It splits the work across two specialized sub-agents — one writes only headlines, one writes only descriptions, each held to its own character limit — because cramming both jobs into a single instruction produced noticeably worse copy. Underneath that sits an experiment-memory system that logs which headline angles already underperformed, so the next round of variants doesn’t repeat last month’s mistakes. The marketer still reviews every line before it goes live; the system gives him fifteen drafts to react to instead of a blank page.
The same blog post lists what the rest of Anthropic’s marketing org got out of comparable setups, and the numbers read like a list nobody bothered to round up for effect: 2.5 hrs → 30 min for drafting customer case studies, a 5× year-over-year productivity gain on one digital-marketing workflow, and a 40% cut in trade-show prep time for the partner-marketing team. None of these are independently audited — it’s Anthropic describing its own internal use of its own product — so treat the multipliers as directional rather than gospel. But the mechanism behind each one is checkable: a named role, a real data feed, a fixed output shape, and a record of what already failed. That’s the part worth stealing, regardless of which company is doing the bragging.
The filter for this list was simple: a named company, a dated source, a describable prompting mechanism, and a number attached to it. A few entries below are self-reported and flagged as such; a few are independently verified by press outside the company. The “source type” column tells you which is which, because that distinction usually gets erased by the time a stat reaches its fifth aggregator blog.
| Company & sector | What they actually changed | The number | Source type |
|---|---|---|---|
| Anthropic Growth marketing | Slash command + two specialized sub-agents + experiment memory for Google Ads copy | 2 hrs → 15 min, ~10× output | Company blog claude.com |
| Brainlabs Media agency | Org-wide skills library built by 1,000 employees inside Claude Cowork over four weeks | ~400 skills / 4 wks | Company case study claude.com/customers |
| Dove (Unilever) Beauty / CPG | Published a 72-page prompting playbook with an inclusive-language glossary for image generators | Industry-cited standard | Brand publication dove.com |
| Heinz CPG / food | Tested single-word and short phrase prompts in DALL·E 2 to confirm brand-shape recognition | 1B+ impressions, +38% engagement | Agency-compiled improvado.io |
| Duolingo Edtech / software | Natural-language code comments as prompts inside GitHub Copilot, org-wide | +25% / +10% dev speed | Primary customer story github.com |
| Superside Creative agency | Batched, systematically varied prompts against custom AI image models from one photoshoot | 10× faster, −75% time/img | Self-reported superside.com |
| Zoom SaaS / video comms | Text-to-video script prompts replacing manual filming for internal training content | 90% faster production | Vendor case study crescendo.ai |
| Rocky Brands Retail / footwear | AI-generated page titles and meta tags at SKU scale via keyword-discovery prompts | +30% search revenue | Vendor case study crescendo.ai |
| Klarna Fintech | AI customer-service assistant handling routine support prompts at scale | Strong launch, partial walk-back | Independent press entrepreneur.com |
| Anthropic engineers Internal tooling | Personal prompt library for teaching, spec interviews, and session memory | Qualitative, widely copied | Independent press xda-developers.com |
This one isn’t a case study so much as a leak of internal habits. A June 2026 XDA report collected prompts that Anthropic’s own Claude Code team members use on themselves, sourced largely from engineer Thariq’s public posts about his own workflow. None of them are clever sentences. Each one restructures how the model behaves for a specific recurring problem.
One spins off the actual work to a background agent while a separate read-only “explore” agent narrates what’s happening in plain English, built originally so Thariq’s non-technical sister could vibe-code a stats site without drowning in developer jargon. Another turns Claude into a tutor that won’t let a session end until it has quizzed the user, one concept at a time, using a built-in question tool — with a hard stopping condition so there’s no nodding along to code nobody understood. A third flips the usual order entirely: instead of writing a spec yourself, you hand Claude a half-finished one and have it interview you about every edge case and tradeoff you forgot to mention, then let it write the finished version. A fourth makes the case for planning complex work in an HTML file rather than Markdown, because past a hundred lines or so nobody re-reads a wall of text, but an HTML page can hold mockups, data-flow diagrams, and color-coded code snippets that a browser renders instantly. The last one is almost embarrassingly simple: at the end of a session, ask Claude to summarize what it learned about your project and suggest what’s worth saving to its memory file, so the next session doesn’t start from zero.
None of these five prompts mention output quality, tone, or creativity once. Every one of them is solving a structural problem — what gets remembered, who gets asked what, and in what format — which is exactly the pattern from Anthropic’s own marketing team above.
Most brands treat a winning prompt as proprietary. Dove did the opposite. In 2024, the brand commissioned a global study and found that one in three women feel pressure to alter their appearance because of images they see online, even when they know those images are AI-generated. Its response wasn’t an ad. It was a 72-page document called the Real Beauty Prompt Playbook, built with Unilever’s own UX researchers alongside outside diversity consultants, that teaches anyone how to prompt an image generator toward more representative output.
The mechanism is straightforward enough to copy today: take a single, fully detailed base description — profession, setting, lighting, pose, all spelled out — and change exactly one variable, usually an ethnicity, body type, or physical trait, then generate both versions and compare them side by side. The gap between the two images shows you precisely what the model defaults to when you don’t specify that detail. It’s a controlled experiment dressed up as a creative prompt, and it’s the same swap-one-variable method behind most of the comparison templates we keep in our running prompt library at BestPrompt.Art — minus the seven-figure research budget.
Where Dove needed seventy-two pages, Heinz needed one word. Marketers typed plain prompts like ketchup, ketchup in outer space, and renaissance painting of ketchup into DALL·E 2 and watched the model consistently render bottle-shaped, Heinz-red results without anyone naming the brand. Improvado’s compiled case data puts the resulting campaign — extended into a public gallery of user-submitted AI ketchup art — at over a billion impressions and a 38% lift in social engagement over benchmark.
The honest takeaway here isn’t “short prompts win.” It’s that no prompt engineering can manufacture brand recognition a company spent a century buying. Heinz could get away with almost no prompt at all because its bottle shape was already baked into the training data of every image model built since. If your brand doesn’t have that kind of visual equity yet, copying Heinz’s one-word approach will mostly just generate generic condiment bottles with nobody’s logo on them.
Superside, a creative-production agency, used its own AI-first rebrand as a six-month proof of concept. The team shot one foundational photoshoot, then trained custom image models on it and generated batch variations for landing pages, video ads, and a twelve-month social content library. Superside reports 10× faster image creation, 75% less time spent per image, and an 85% lower cost per image compared with its prior production process.
Here’s the asterisk: this is an agency describing its own internal rebrand, with no third-party audit attached, so treat the specific multipliers as directional rather than load-bearing. What is checkable is the method underneath the number — one consistent source shoot, a fixed base prompt, systematic variation of a handful of variables — which is exactly the batching discipline that separates a usable image-prompt workflow from a pile of one-off generations nobody can reproduce.
Not every prompt win is about marketing copy or campaign visuals. At Duolingo, the prompt is a natural-language comment typed straight into the code editor, and GitHub Copilot turns it into a suggested function. GitHub’s own customer story reports a 25% increase in developer speed for engineers working in an unfamiliar repository, and a 10% increase for developers who already know the codebase — useful nuance, since it means the tool helps newcomers more than veterans, not the other way around most people assume.
Worth flagging plainly: plenty of secondary articles attribute a 67% faster median code-review time to Copilot itself. GitHub’s own case study credits that specific number to a separate Slack notification integration Duolingo built, not to AI-generated code suggestions. It’s a small distinction that most aggregator posts erase on the way to a punchier headline, and it’s exactly the kind of overclaiming this article is trying not to repeat.
In February 2024, Klarna’s OpenAI-built customer-service assistant handled 2.3 million conversations in its first month across more than 35 languages — work the company said was equivalent to roughly 700 human agents. Resolution time dropped from 11 minutes to under 2. Repeat inquiries fell 25%. Klarna projected the system would add around $40 million to 2024 profit. For over a year, this was the single most-cited “AI replaced human jobs” story in the industry.
Then, in May 2025, CEO Sebastian Siemiatkowski told Bloomberg the company had gone too far. Klarna began rehiring human agents, specifically to make sure customers always have a person to talk to for the complex, emotionally loaded cases the AI handled badly. The launch-week metrics were not fabricated. They measured the easy 90% of conversations well and said almost nothing about the hardest 10%, which is exactly where the quality complaints accumulated.
The lesson isn’t “don’t use AI for customer service.” It’s that a prompt-driven workflow can be a genuine win on the average case and a genuine liability on the tail case at the same time, and only one of those shows up in a launch-week press release.
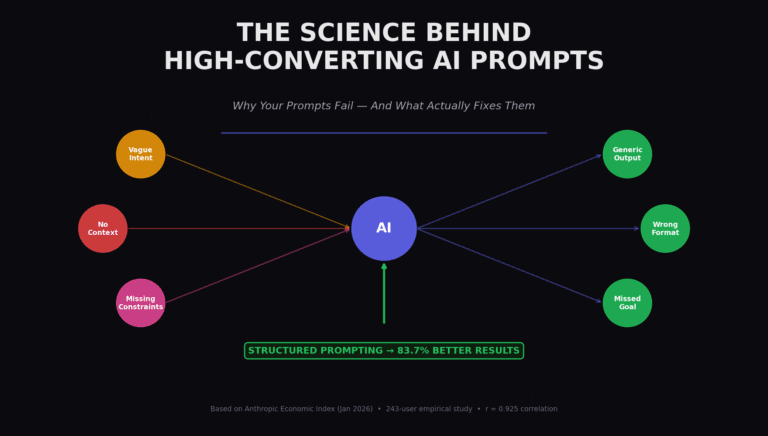
Strip the company names off all ten cases above and the same five ingredients show up every time. A defined role — Anthropic’s sub-agents aren’t told to “write good ad copy,” they’re told exactly which half of the job is theirs. Live context instead of a guess — the slash command pulls real campaign data rather than asking the model to imagine plausible numbers. A strict output format — fifteen headlines, four descriptions, packaged as a CSV, not “some ideas.” Explicit constraints or a glossary — Dove’s playbook is essentially nothing but specificity rules. And a memory loop that survives the session — what failed last time gets fed back in, instead of every run starting from a blank page.
Klarna’s case is instructive precisely because it had four of those five and was missing the fifth: a human checkpoint sized to the difficulty of the case, not just the volume. The easy 90% never needed one. The hard 10% needed it badly, and didn’t get it until the brand damage was already visible in the satisfaction scores.
Strip away the industry labels and Dove’s swap-one-variable method and Superside’s fixed-source-plus-batch-variation method are the two techniques most serious AI image accounts already lean on, often without naming them. The piece most people skip is the memory loop: Anthropic’s marketers don’t re-litigate which headline angle bombed last month, because the system remembers. Most individual prompt experimenters do re-litigate it, every single session, because nothing is logging the outcome. Keeping even a simple running record of which structures held up across model updates — which is the entire premise behind the prompt template index we maintain at BestPrompt.Art — is the cheapest version of the exact mechanism behind every win in this article.
Everything specific in this article has an expiration date. The slash command will get renamed, Cowork will ship new features, and a newer model will make today’s exact wording obsolete within a couple of release cycles. The role-plus-context-plus-memory-plus-checkpoint architecture underneath it won’t. That’s the only part actually worth stealing.