Battle-tested, copy-paste-ready prompts that senior developers actually use — with the reasoning behind each one, real-world gotchas, and honest data on what you can actually expect.
- The gap is real, but it’s a prompt gap, not an AI gap. Stack Overflow’s 2025 survey of 49,000+ developers found 84% use AI tools — yet 46% distrust the output and 45% spend more time debugging AI code than writing it themselves. The difference between those groups is almost entirely how they prompt.
- Good prompts follow structure. Every high-performing prompt in this post uses some combination of: role assignment, explicit constraints, output format specification, and context about your codebase. Vague requests get vague code.
- The 55% productivity gain headline is real — but conditional. GitHub’s 2024 research clocked task completion dropping from 2 hours 41 minutes to 1 hour 11 minutes. That gain holds when you give AI sufficient context. Without it, you often lose time, not gain it.
- These 25 prompts cover the full workflow: code generation, debugging, refactoring, testing, documentation, architecture, security review, performance optimization, and learning.
- Honest warning: copy-pasting prompts without adapting them to your tech stack and project conventions will produce mediocre results. Treat every prompt here as a starting template, not a magic incantation.
- Quick start: If you have five minutes, jump to Prompt #3 (Root-Cause Debugger) and Prompt #7 (Code Review). Those two alone will save most developers 2–3 hours a week.
There’s a moment most developers recognize: you type a request into Claude or ChatGPT, get back something that almost works, spend 20 minutes massaging it into shape, and walk away thinking “that was barely faster than writing it myself.” That’s not an AI problem. That’s a prompt problem.
I’ve been paying close attention to how developers actually use these tools across the teams I work with — not in controlled demos but in real production codebases with legacy debt, inconsistent naming conventions, and all the messy reality that benchmarks ignore. The difference between developers who genuinely save hours and those who don’t comes down almost entirely to how they structure their requests.
The prompts in this guide aren’t magic phrases. They’re structured frameworks with specific ingredients that give language models enough context to produce useful output on the first attempt. Get the structure right, and the model — whether it’s Claude Sonnet, GPT-5, or Gemini — will generally deliver something that actually fits your codebase.
Every prompt here has been tested against Claude Sonnet 4.6, GPT-5, and Gemini 2.5 Pro. Where a particular prompt works significantly better with one model, I’ve flagged it. In 2026, the major models have converged enough that well-structured prompts work across all of them — the bigger variable is context quality, not model choice.
Before diving into the prompts, it’s worth being honest about what research tells us — including the parts that don’t make it into marketing copy.
That 55% figure — task completion dropping from 2 hours 41 minutes to 1 hour 11 minutes — is real, but it comes with an asterisk. Stack Overflow’s survey makes clear that 66% of developers regularly encounter AI output that’s “almost right but not quite.” That “almost” is where hours get swallowed. Good prompts reduce the almost-but-not-quite rate dramatically.
The trust problem is worth addressing directly. Stack Overflow’s CEO Prashanth Chandrasekar put it plainly: “AI is a powerful tool, but it has significant risks of misinformation or can lack complexity or relevance.” That’s not a reason to avoid AI tools — it’s a reason to prompt better and verify always.
Developers who use AI tools daily report higher satisfaction and productivity than infrequent users — not because the tools improved, but because they learned what the tools are actually good at and adjusted their prompts accordingly. If you had a frustrating experience with AI coding tools six months ago, it’s worth retrying with the structure in this guide.
Every high-performing prompt I’ve seen follows some version of this structure, which the developer community has started calling CRTSE. It’s not the only framework — GitHub Copilot engineers talk about “Role + Task + Constraints + Format” — but the underlying logic is identical: give the model enough context to eliminate guesswork.
One thing worth noting for 2026: as developer Mohit Khare documented, the newest models (Claude Sonnet 4.6, GPT-5) follow instructions much better than their predecessors, which means you don’t need to over-engineer prompts the way you did in 2023–2024. The framework above is the floor, not the ceiling.
These are the prompts developers use when they need to produce new code, not just fix existing code. The key principle: the more context you provide about your existing patterns, the less cleanup work you’ll do afterward.
The most common generation task. The key is forcing the model to stay within your actual tech stack instead of defaulting to tutorial-style boilerplate.
You are a senior [Node.js / Python / Go] developer working on a [Express / FastAPI / Gin] application.

Create a [POST / GET / PUT / DELETE] [/api/endpoint-path] endpoint that does the following:
- [Primary function, e.g. "creates a new user record"]
- [Secondary behavior, e.g. "validates the request body against this schema: {schema}"]
- [Error handling requirement, e.g. "returns structured JSON errors, never exposes stack traces"]

Constraints:
- Use [your ORM/database library, e.g. Prisma / SQLAlchemy / GORM]
- Follow this error handling pattern: [paste one example from your codebase]
- Input validation using [Zod / Pydantic / validator, etc.]
- Include inline comments only where the logic is non-obvious
- No console.log / print statements in production paths

Existing pattern to match (paste a similar endpoint from your codebase):
[paste example here]
Generates database schema with migrations, including indexes, constraints, and foreign keys — often the most time-consuming mechanical part of building a new feature.
You are a database engineer. Generate a [PostgreSQL / MySQL / SQLite] schema and [Prisma / Alembic / Flyway] migration for the following data model:

Entity: [EntityName]
Fields:
- id: [UUID / auto-increment integer], primary key
- [field_name]: [type], [nullable / not null], [unique if needed]
- [field_name]: [type], foreign key referencing [other_table].[field]
- created_at, updated_at: timestamps, auto-managed

Constraints:
- Add indexes on: [list frequently queried fields]
- Unique constraint on: [list combination if needed]
- Cascade behavior on delete: [restrict / cascade / set null]

Existing migration style (paste one example):
[paste example migration file]

Output: schema definition + migration file only. No explanatory prose.
Frontend developers spend a disproportionate amount of time on prop drilling, type declarations, and wiring up state. This prompt handles the scaffolding so you can focus on the logic.
You are a senior React + TypeScript developer. Build a [ComponentName] component with these specs:

Purpose: [one sentence explaining what this component does]

Props:
- [propName]: [TypeScript type] — [brief description]
- [propName]: [TypeScript type] — [optional or required]

State management: [useState only / useReducer / Zustand / React Query]
Styling: [Tailwind CSS / CSS modules / styled-components]

Behaviors:
- [User interaction, e.g. "clicking the submit button calls onSubmit(formData)"]
- [Loading state, e.g. "shows skeleton while isLoading is true"]
- [Error state, e.g. "displays inline error message below the field"]

Accessibility: keyboard navigable, proper aria labels, focus management
Do NOT: use any hooks not listed above, add animations (handled separately)

Existing component to match for style:
[paste a similar component]
Automation scripts are a surprisingly strong use case for AI. Because they’re self-contained, there’s less codebase context to provide — and the model can produce something runnable much more reliably.
Write a [Python / Bash / Node.js] script that does the following:

Task: [describe what the script should do in plain English]

Inputs:
- Command-line args: [arg1] ([type/description]), [arg2] ([optional, default: X])
- Environment variables: [VAR_NAME] — [what it controls]

Outputs:
- [what gets written, printed, or returned on success]
- Exit codes: 0 on success, 1 on [specific failure condition], 2 on [another]

Error handling:
- If [condition], print "[specific message]" to stderr and exit [code]
- Never suppress errors silently

Requirements:
- No external dependencies beyond [specific list, or "stdlib only"]
- Idempotent: running twice should produce the same result
- Add usage help accessible via --help flag
One of the highest-signal prompts in day-to-day work. Give the model example input, expected output, and edge cases — and it will write transformation logic that would take a human 30–45 minutes to get right.
Write a pure function in [language] that transforms data from format A to format B.

Input example:
[paste actual JSON/object/array]

Expected output:
[paste expected result]

Edge cases to handle:
- If [field] is null/missing: [behavior]
- If [nested field] is an empty array: [behavior]
- If [value] exceeds [limit]: [behavior]

Requirements:
- Pure function (no side effects)
- TypeScript strict mode compatible (if applicable)
- Include JSDoc / docstring with @param and @returns
- O(n) time complexity or better

Write the function and a brief explanation of the algorithm. No usage examples needed.
Instead of generating one function at a time, use this to scaffold an entire module — including exports, types, and test file structure — in a single pass.
Scaffold a [module/service/class] called [Name] in [language/framework].

Responsibilities (this module should handle):
1. [responsibility 1]
2. [responsibility 2]
3. [responsibility 3]

Public interface (what gets exported):
- [functionName(params)]: [return type] — [what it does]
- [functionName(params)]: [return type] — [what it does]

Internal dependencies:
- [dependency, e.g. "database client passed via constructor injection"]
- [dependency, e.g. "logger instance from ../utils/logger"]

Do NOT implement business logic — use TODO comments for each method body.
Output: the module file + a corresponding test file with test stubs only.
Debugging is arguably where AI tools earn their keep most clearly — provided you give the model enough context. The most common mistake: pasting just the error message without the stack trace, relevant code, or description of what you expected to happen.
This is the prompt I’d recommend starting with if you only try one. It forces structured diagnosis rather than jumping straight to a fix — which is exactly what a good senior developer does.
I'm debugging an issue in a [language/framework] application. Help me find the root cause.

Error message:
[paste full error message]

Stack trace:
[paste full stack trace]

Code where the error occurs:
[paste the function/method — ideally 20–60 lines of context]

What I expected to happen:
[describe expected behavior]

What actually happens:
[describe actual behavior]

What I've already tried:
[list any debugging steps you've already taken]

Please:
1. Identify the most likely root cause (not just the symptom)
2. Explain WHY this error occurs in plain terms
3. Suggest 2–3 possible fixes with trade-offs for each
4. Flag any related issues you notice in the code, even if not causing this error
Race conditions and async bugs are notoriously hard to reproduce and reason about. This prompt structures the model’s thinking around the timing and ordering that makes async bugs so slippery.
I have an intermittent bug that may be a race condition or async ordering issue.
Language/framework: [language]
Async model: [callbacks / promises / async-await / goroutines / threads]

Affected code:
[paste the relevant async code sections]

Symptom: The bug occurs when [describe trigger — e.g. "multiple users submit the form simultaneously"].
Frequency: approximately [X% of the time / only under load / only in production].

Please:
1. Identify potential race conditions or ordering issues in this code
2. Explain the scenario under which each could trigger
3. Suggest fixes that eliminate the race condition, not just reduce its frequency
4. If relevant, suggest how to write a test that reliably reproduces the issue
Profiler output is notoriously opaque. This prompt turns raw profiler data into an actionable diagnosis.
I have profiler output from a [Node.js / Python / Java / Go] application that's performing
slower than expected.

Performance target: [e.g., "API response under 200ms, currently averaging 900ms"]

Profiler output / flame graph summary:
[paste profiler output, top N functions, or describe where time is spent]

Database query analysis (if available):
[paste slow query log or EXPLAIN output]

Relevant code sections for the hot paths:
[paste the functions showing up in the profiler]

Please:
1. Identify the top 3 performance bottlenecks by likely impact
2. For each: explain the cause and suggest a specific fix
3. Estimate the order-of-magnitude improvement each fix might yield
4. Flag any anti-patterns that could cause future performance regressions
Memory issues are one of the hardest bugs to diagnose manually. Give the model the right signals and it can often identify the pattern within seconds.
I'm investigating a memory leak in a [language/runtime] application.

Symptoms:
- Memory grows from [X MB] to [Y MB] over [time period]
- [Any other observations: GC behavior, heap dumps, specific operations that trigger growth]

Heap snapshot / memory profile summary (if available):
[paste key data — e.g., object type counts, retained sizes]

Code sections I suspect (or common leak patterns for this framework):
[paste relevant sections, e.g. event listener setup, closure-heavy code, caches]

Our environment:
- Runtime version: [e.g., Node.js 22, Python 3.12]
- Long-running process: [yes/no]

Please:
1. Identify likely leak sources based on the symptoms and code
2. Explain the retention mechanism for each (why the GC can't reclaim it)
3. Suggest targeted fixes
4. Recommend monitoring strategies to confirm the fix in production
Dependency hell is a time sink that AI handles surprisingly well, especially when you give it the full context of your package manifest.
I'm dealing with a dependency conflict in a [npm / pip / cargo / maven] project.

Error output:
[paste the full dependency resolution error]

My package manifest (package.json / requirements.txt / Cargo.toml):
[paste full file or relevant sections]

What I'm trying to add / upgrade:
[package name and target version]

Constraints:
- Cannot upgrade [specific dependency] past [version] due to [reason]
- Must maintain compatibility with [Node.js / Python / etc. version]

Please:
1. Explain exactly what the conflict is and why it exists
2. Suggest the minimum set of changes to resolve it
3. Flag any compatibility risks with the suggested resolution
4. If a clean resolution is impossible, explain the trade-offs of each compromise option
Code Review & Refactoring
These prompts turn AI into the kind of thorough code reviewer most teams don’t have time to be for each other. The key is being specific about what you want reviewed — broad “review this code” requests produce generic, surface-level feedback.
Run this before every pull request. It surfaces issues that should be caught before reviewers see the code — not after.
Review this [language] code before it goes into a pull request. Be thorough and honest.

Code:
[paste the code]

Context:
- This is part of [describe the feature/module]
- It will handle [describe the scale: e.g. "~1000 requests/hour" or "batch job running nightly"]
- Current test coverage for this module: [%]

Review for:
1. Bugs and logic errors (be specific about conditions under which they trigger)
2. Security issues (injection, exposure, improper auth, etc.)
3. Edge cases that aren't handled
4. Performance issues that matter at the stated scale
5. Readability and maintainability concerns
6. Missing or inadequate error handling

Format your response as:
- CRITICAL: [issues that must be fixed before merge]
- IMPORTANT: [issues that should be fixed]
- MINOR: [suggestions and style notes]
- LOOKS GOOD: [what's done well — be specific]
General code review and security review are different skills. This prompt focuses specifically on security, going deeper than a general review would.
Perform a security audit on this [language] code. Focus exclusively on security issues.

Code:
[paste the code]

Context:
- Entry point: [is this user-facing? internal API? admin only?]
- Authentication: [how is the caller authenticated?]
- Data handled: [PII / financial / public / internal]
- External integrations: [databases, third-party APIs, file system, etc.]

Specifically check for:
- Injection vulnerabilities (SQL, command, LDAP, etc.)
- Authentication/authorization bypasses
- Sensitive data exposure (logging, error messages, API responses)
- Input validation gaps
- Insecure direct object references
- Missing rate limiting or abuse prevention
- Cryptographic issues (weak algorithms, predictable tokens, etc.)

For each finding: severity (CRITICAL / HIGH / MEDIUM / LOW), description of the attack vector, and recommended fix.
Do not include style or performance feedback — security only.
Throwing legacy code at an AI and asking it to “clean this up” produces unreliable results. This structured approach gets you a phased plan you can actually execute safely.
I need to refactor legacy [language] code. Help me create a safe, incremental plan.

Current code:
[paste the code]

Problems I'm aware of:
- [known issue 1]
- [known issue 2]

Constraints:
- Cannot change the public interface / existing callers depend on current API signatures
- Test coverage: [describe current state — low / moderate / high]
- Risk tolerance: [e.g., "this is called in the payment flow, changes must be very safe"]

Please:
1. Identify all refactoring opportunities in priority order
2. Suggest an incremental refactoring sequence (which changes to make first, second, etc.)
3. For each step: describe what changes, what risk it introduces, and what tests to add before making the change
4. Flag any refactorings that look tempting but are actually risky given the constraints
Sometimes you know something is wrong with a piece of code but can’t articulate exactly what. This prompt names the patterns so you can fix them deliberately.
Analyze this [language] code for code smells and design issues. Don't fix anything —
just identify and explain the problems.

Code:
[paste the code]

For each issue found:
- Name the specific anti-pattern or code smell (e.g., "God Class," "Shotgun Surgery," "Feature Envy")
- Explain why it's a problem in this specific context
- Rate the severity of leaving it as-is: [High / Medium / Low]
- Suggest the appropriate refactoring pattern to address it (name the pattern, don't implement it)

Focus on structural issues, not style preferences.
When code works but is unnecessarily complex, this prompt finds the simplification without changing behavior.
Simplify this [language] code without changing its behavior or public interface.

Code:
[paste the code]

Goals (pick what applies):
□ Reduce lines of code
□ Remove unnecessary abstractions
□ Flatten nested conditions
□ Remove dead code paths
□ Replace verbose constructs with language idioms

Hard constraints:
- Do not change function signatures
- Do not change error handling behavior
- Do not introduce new dependencies
- Must pass the same tests as the original

Output:
1. Simplified code
2. For each change: what you changed and why it's equivalent
3. Any behavior changes I should verify manually
Testing Prompts
Test generation is one of AI’s most reliable use cases because tests have a well-defined structure and the correctness criteria are explicit. The prompts below push beyond simple happy-path tests to the edge cases that actually matter.
Most AI-generated tests cover the happy path and stop there. This prompt forces coverage of the cases that matter most.
Write comprehensive unit tests for this [language] code using [Jest / pytest / Go testing / JUnit].

Code to test:
[paste the function/class/module]

Testing framework conventions (paste one example test from your codebase):
[paste example]

Required coverage:
1. Happy path: all valid inputs producing expected outputs
2. Boundary conditions: min/max values, empty inputs, single-element collections
3. Error cases: invalid inputs, missing required fields, type mismatches
4. Null/undefined/None handling
5. [Any domain-specific edge cases you know about]

Mocking:
- Mock these external dependencies: [list databases, APIs, file system, etc.]
- Use [your mocking library, e.g. jest.mock / unittest.mock / testify/mock]

Do NOT:
- Test implementation details (test behavior, not internals)
- Write tests that only pass in isolation (no global state assumptions)
- Add comments explaining what each test does — the test name should be self-explanatory

Test naming convention: [describe your convention, e.g. "should_[expected]_when_[condition]"]
Integration tests require understanding the flow between components. This prompt provides that flow as context.
Write integration tests for the following user journey using [Playwright / Cypress / Supertest].

User journey to test:
1. [step 1, e.g. "User submits login form with valid credentials"]
2. [step 2, e.g. "System redirects to dashboard"]
3. [step 3, e.g. "User creates a new resource via the form"]
4. [step 4, e.g. "Resource appears in the list view"]

API endpoints or UI components involved:
[list the endpoints / pages / components]

Test database state (what should exist before the test runs):
[describe seed data needed]

Also write tests for these failure scenarios:
- [failure scenario 1, e.g. "login with incorrect password"]
- [failure scenario 2, e.g. "submit form with missing required field"]

Cleanup: [describe how to reset state after each test — delete created records, reset mocks, etc.]
Use this when you have existing tests but suspect there are gaps. More targeted than adding random tests until the coverage number goes up.
Analyze this code and its existing tests to identify coverage gaps.

Production code:
[paste the code]

Existing tests:
[paste the test file]

Current coverage report (if available):
[paste coverage output or describe uncovered lines]

Please:
1. Map out all the code paths through this function/module
2. Identify which paths are NOT covered by existing tests
3. For each uncovered path: explain the risk of not testing it (Low / Medium / High) with reasoning
4. Write the missing tests in order of risk priority
5. Flag any existing tests that are testing the wrong things or are likely to produce false confidence
Documentation Prompts
Documentation is the task developers most consistently skip and then regret. These prompts make it fast enough that there’s no excuse to skip it.
Produces documentation that an external developer could actually use — not just a reformatted version of the code comments.
Generate comprehensive API documentation for this endpoint / function.

Code:
[paste the endpoint/function]

Target audience: [internal developers / external API consumers / both]
Documentation format: [OpenAPI 3.0 YAML / Markdown / JSDoc / Python docstring]

Include:
- Purpose and when to use this endpoint
- All parameters with types, constraints, and whether required or optional
- Request body schema with field descriptions
- All possible response codes and what triggers each
- Response body schema with field descriptions
- At least 2 realistic usage examples (curl for APIs, code for functions)
- Known limitations or gotchas
- Related endpoints/functions

Do NOT include implementation details or internal logic — this is for consumers of the API, not maintainers.
A good README is the difference between a project that gets used and one that gets ignored. This prompt produces one with the right structure.
Generate a README.md for this project.

Project description: [what it does in one sentence]
Target users: [who this is built for]
Tech stack: [languages, frameworks, key dependencies]

Key information to include:
- Prerequisites and system requirements
- Installation steps (tested, sequential, copy-pasteable)
- Configuration (environment variables with examples)
- Basic usage examples (real commands, not placeholders)
- How to run tests
- How to contribute (if open source)
- License

Context from the codebase (paste package.json / pyproject.toml / README draft if any):
[paste]

Tone: [technical and concise / friendly and approachable]
Do NOT use marketing language, vague descriptions, or placeholder examples.
Every command in the README must actually work.
Architecture & Design
These prompts are slower to return value — architecture discussions require more back-and-forth — but they’re where AI can help you avoid decisions you’ll regret for months.
Forces structured thinking about technical decisions — and produces a document that explains your reasoning to future team members.
Help me write an Architecture Decision Record (ADR) for the following decision.

Decision to document: [e.g., "Which message queue to use for our event-driven system"]

Options I'm considering:
1. [Option A, e.g. "RabbitMQ"] — [brief description of why it's a candidate]
2. [Option B, e.g. "Apache Kafka"] — [brief description]
3. [Option C, e.g. "AWS SQS"] — [brief description]

Our constraints and requirements:
- Scale: [e.g., "~50,000 events/day, expected to reach 1M within 18 months"]
- Team expertise: [e.g., "team has experience with X, not Y"]
- Operational: [e.g., "managed service preferred — no dedicated ops team"]
- Cost: [e.g., "under $X/month at current scale"]
- Existing infrastructure: [e.g., "already on AWS, using ECS"]

Format as a proper ADR with sections: Status, Context, Decision, Consequences (positive and negative), Alternatives Considered.
Before committing to an architecture, use this prompt to stress-test it. A second opinion that doesn’t have social incentives to agree with you.
Critique this system design. Be honest and specific — I want the problems, not validation.

System description:
[describe the proposed architecture — components, data flow, key decisions]

(Optional) Architecture diagram description or ASCII diagram:
[paste if available]

Scale targets:
- Users: [e.g., "10,000 concurrent users, 500,000 registered"]
- Data volume: [e.g., "2TB of documents, growing 20GB/month"]
- Availability target: [e.g., "99.9% uptime"]

Please evaluate:
1. Single points of failure
2. Scalability bottlenecks (where will this break first under load?)
3. Data consistency risks
4. Security surface area concerns
5. Operational complexity (will a small team be able to run this?)
6. Cost at the stated scale

Rate overall design risk: Low / Medium / High, with reasoning.
Be specific. "This could have issues" is not useful — name the issue.
Learning & Exploration
AI tools shine as learning companions when you ask structured questions rather than just “explain X to me.” These prompts produce deeper understanding, not just summaries.
For learning a new concept, framework, or language feature. Produces understanding you can apply, not just recognition.
Explain [concept/feature/pattern] to me. My background: [your experience level and relevant context].

I want to understand:
1. What problem this solves (specifically — not just "it makes code better")
2. How it works internally (one level below the surface API)
3. When to use it vs. [common alternative]
4. When NOT to use it (the cases where it's the wrong choice)
5. The most common mistakes developers make with it
6. One non-trivial example that shows something you can't do without this concept

Keep examples in [language]. Use the level of detail appropriate for someone who [describe your level, e.g., "understands closures and async/await but hasn't worked with Rust's borrow checker"].
Drop unfamiliar code into this prompt when joining a project, inheriting a module, or returning to code you wrote months ago.
I need to understand this code I didn't write (or haven't read in a long time).
Give me a thorough explanation oriented toward someone who needs to modify it safely.

Code:
[paste the code]

Please explain:
1. What this code does at a high level (purpose and context, if inferrable)
2. Walk through the logic step by step — don't skip parts that look obvious
3. What the key assumptions are (what inputs, state, or environment does it depend on?)
4. What would break if [specific thing you might want to change]
5. What parts of this code are fragile or surprising
6. What you'd want to know from the original author before touching this

Do not rewrite or improve the code — just explain it.
Prompt Comparison: Use-Case Reference
Quick reference for matching the right prompt to your situation.
| # | Prompt Name | Best For | Time Saved (est.) | Works Best With |
|---|---|---|---|---|
| 1 | Full-Stack Endpoint Generator | New feature development | 45–90 min | Claude, GPT-5 |
| 2 | Schema & Migration Generator | Database modeling | 30–60 min | Claude, Gemini |
| 3 | React Component Generator | Frontend scaffolding | 30–60 min | Claude, Cursor |
| 4 | CLI Tool Generator | Automation scripts | 60–120 min | Any model |
| 5 | Data Transformation | ETL / data wrangling | 30–45 min | Claude, GPT-5 |
| 6 | Module Scaffold | New module setup | 20–40 min | Any model |
| 7 | Root-Cause Debugger | Frustrating bugs | 60–240 min | Claude (strong reasoning) |
| 8 | Race Condition Analyzer | Intermittent async bugs | 120+ min | Claude |
| 9 | Performance Profiler | Slow endpoints/jobs | 60–120 min | GPT-5, Claude |
| 10 | Memory Leak Detector | Growing memory usage | 90–180 min | Claude |
| 11 | Dependency Resolver | Package conflicts | 30–60 min | Any model |
| 12 | Pre-Commit Code Review | Before every PR | 20–40 min/PR | Claude, GPT-5 |
| 13 | Security Audit | Security-sensitive code | 60–120 min | Claude |
| 14 | Legacy Refactoring Plan | Technical debt | Hours of planning | Claude |
| 15 | Code Smell Identifier | Design review | 30–60 min | Claude, GPT-5 |
| 16 | Targeted Simplification | Overengineered code | 20–45 min | Any model |
| 17 | Unit Test Suite | Test coverage | 45–90 min | Any model |
| 18 | Integration Test Writer | E2E flows | 60–120 min | Claude, GPT-5 |
| 19 | Coverage Gap Analysis | Improving existing tests | 30–60 min | Claude |
| 20 | API Documentation | Public/internal APIs | 30–60 min | Any model |
| 21 | README Generator | New projects | 20–40 min | Any model |
| 22 | ADR Generator | Key technical decisions | 60–90 min | Claude |
| 23 | System Design Critique | Architecture review | 120+ min | Claude |
| 24 | Concept Deep Diver | Learning new tech | 60–120 min | Claude, Gemini |
| 25 | Codebase Onboarding | Understanding unfamiliar code | 60–180 min | Claude |
The “time saved” figures above are estimates based on common developer experiences, not controlled studies. Your actual results will depend heavily on how much context you provide, how complex the codebase is, and how much review you need to do afterward. The GitHub research showing 55% task completion speed gains (Moe et al., 2025) is the most rigorous benchmark available. Individual results will vary. These prompts don’t eliminate the need for experienced judgment — they reduce mechanical work so you can focus that judgment where it matters.
Frequently Asked Questions
Do these prompts work with any AI coding tool, or only specific ones?
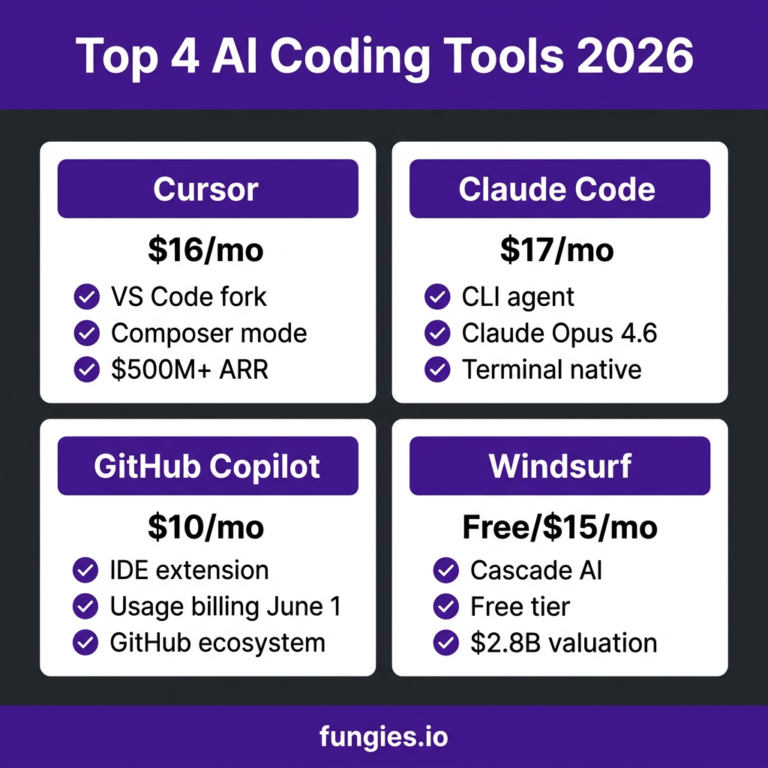
Every prompt in this guide has been tested on Claude Sonnet 4.6, GPT-5, and Gemini 2.5 Pro. They also work in IDE-integrated tools like GitHub Copilot Chat and Cursor, though you’ll sometimes need to trim them slightly for context window efficiency in those environments.
The structure matters more than the model. If you switch models, you may get stylistically different output — Claude tends to be more thorough in its reasoning, GPT-5 is often more concise — but the underlying quality should be comparable if you’ve provided the same context.
How much context is too much? My prompts are getting very long.
For most tasks, 200–600 lines of context is a reasonable upper bound. Beyond that, models can lose focus on the parts that matter. If you’re pasting an entire file that’s 1,000+ lines, consider trimming to just the relevant function and its immediate dependencies.
One reliable signal: if you have to scroll a long time to get past your pasted code before seeing the actual question, your prompt is probably too long. Summarize the parts that aren’t directly relevant to the specific task.
Is it safe to paste production code into AI tools?
This is a legitimate concern with a nuanced answer. Most major AI providers (Anthropic, OpenAI, Google) offer enterprise plans where your inputs aren’t used for model training. Check the specific terms for the product tier you’re using.
At a minimum: never paste credentials, API keys, or personally identifiable data. For sensitive business logic or proprietary algorithms, consider whether the productivity gain justifies the disclosure. Many teams use anonymized or simplified versions of sensitive code when prompting.
The AI often gives me code that almost works but has subtle bugs. How do I reduce this?
The “almost right” problem is the most consistent pain point in the Stack Overflow 2025 survey — 66% of developers report it. Two things help most: (1) provide more specific constraints in your prompt, especially error handling and edge case behavior, and (2) always ask the model to list its assumptions. Assumptions are where subtle bugs live.
Also: chain your prompts. Use a second prompt to specifically ask the model to review the code it just generated for edge cases and bugs. The model often catches its own mistakes when asked to review its output separately.
Should I use AI for code review or stick with human reviews?
Use both, for different things. AI code review (Prompt #12 in this guide) is excellent for catching logic errors, security issues, and edge cases — things that are deterministic and don’t require business context. Human reviewers are better at evaluating whether a feature should exist at all, whether the approach fits the team’s conventions and direction, and subtle architectural concerns.
A practical workflow many teams use: run AI review before requesting human review, so the human reviewer isn’t doing mechanical error-finding and can focus on higher-level concerns.
How do I get AI to follow my team’s coding conventions?
The most reliable method is to paste one example of existing code from your codebase that demonstrates the conventions you want followed — not describe them in prose. Models learn by example better than by instruction for stylistic and pattern-based requirements.
For teams using Cursor or Claude Code, you can define persistent system prompts or CLAUDE.md / .cursorrules files that describe your conventions. These apply to every request in the project without needing to repeat them each time.
Can AI actually help with architecture decisions, or is it just pattern-matching?
Honestly, both. AI architecture advice is most valuable as a structured thinking tool — it can surface trade-offs you haven’t considered, ask clarifying questions, and challenge assumptions. It’s weakest on very company-specific constraints (team capabilities, budget details, strategic direction) that aren’t visible in the prompt.
Use Prompt #22 (ADR Generator) and Prompt #23 (System Design Critique) as a starting point and a stress test, not as a final decision-maker. The value is in the structured reasoning it forces, not in trusting its recommendations blindly.
What’s the most common mistake developers make when prompting AI for code?
Not providing enough context about the existing codebase. The model has no idea what patterns your team uses, which libraries you’ve already included, how you handle errors, or what the calling code looks like. When you give it none of that context, it defaults to tutorial-style code that technically works but doesn’t fit your project.
The second most common mistake: accepting the first response without questioning it. Treat AI output the way you’d treat code from a capable-but-new team member: assume it needs review, not blind trust.
How often should I update my prompts?
Revisit your core prompts when the AI model you’re using gets a major update, when your tech stack changes significantly, or when you notice the output quality degrading. The 2024–2026 period has seen major model improvements, so prompts written for GPT-4 or Claude 2 often over-specify — newer models need less hand-holding and benefit from more concise prompts.
As a general rule: if a prompt consistently produces output that needs significant editing, that’s a signal the prompt needs updating, not that AI can’t do the task.
Can I use these prompts in agentic tools like Claude Code or Cursor Agents?
Yes, with adjustments. Agentic tools (Claude Code, Cursor’s agent mode) can read your actual files and run tests, so you don’t need to paste code into the prompt — instead, describe what you want and let the agent navigate the codebase. The structural principles in this guide still apply: be specific about constraints, expected behavior, and what NOT to do.
One important difference: agentic tools can make multiple changes across files. Be more explicit about scope — “only modify the UserService class, don’t touch the tests” — to prevent unintended changes across the codebase.
How do I know when AI is out of its depth on a task?
A few reliable signals: the model starts hedging heavily (“this might work depending on your setup”), it generates plausible-sounding but clearly incorrect code, it gives contradictory advice in consecutive messages, or it starts inventing library APIs that don’t exist (hallucination).
For highly specialized domains — low-level systems programming, novel cryptographic implementations, extremely domain-specific business logic — AI is most useful as a sounding board and for boilerplate, not as the primary implementation source. Verify anything in these areas with primary sources and peer review.
What’s the best free option for developers who can’t afford paid AI tools?
Claude.ai has a free tier that works well for most prompts in this guide. Google’s Gemini 2.5 Pro also has a generous free tier with strong coding capability. GitHub Copilot has a free tier for individual developers as of 2024 (limited completions per month).
For most developers, the free tier of any major model is sufficient for learning prompt engineering. Once you’re using AI daily for production work, the paid tiers pay for themselves within a week of saved time.
Final Thoughts
The honest version of the AI coding tools story isn’t “they save everyone hours automatically.” It’s “developers who learn to prompt well save significant time; developers who don’t often break even or come out behind.” The gap between those two groups is the skill in this guide.
Start with three or four prompts from different categories — one for generation, one for debugging, one for code review. Adapt them to your specific stack. Notice where the output quality is high and where it needs work, then adjust the constraints accordingly. After a week or two of deliberate practice, the structure becomes intuitive.
The Stack Overflow 2025 survey finding that daily AI users report substantially higher satisfaction than infrequent users isn’t because the tools are more reliable for those people — it’s because frequency builds the judgment to know when to trust the output and when to scrutinize it. That judgment is the real skill. These prompts are just a structured way to start building it.
More From BestPrompt.art
AI Tools and Platforms 2025
ChatGPT Prompts for Frontend Developers to Build Faster
AI in community management: 10 ChatGPT Prompts That Will Change Your Game
AI Prompt Tricks to Instantly Improve Your Code
2025 Midjourney Tips: Getting Started Guide
ChatGPT vs Claude vs Gemini: What the Benchmarks Actually Say
Generative AI for Designers: What’s Working in 2025 (And What’s Just Hype)
AI Coding Prompts Developers Use to Save Hours: Best Guide
The Prompt Engineering Stack —The Mistake Costing You Results Every Single Month
How Developers Use AI Prompts to Write Code Faster: BestGuide
How Prompt Keywords Optimize LLM Performance: What Actually Works in 2026
The AI Prompts Top Developers Use Every Day – Best Guide
How to Use AI to Write Cleaner, More Efficient Code